

Quick answer: what API integration is
An API integration connects two or more applications through their APIs so they exchange data and trigger actions automatically. Say a visitor fills in a web form. The form tool creates a CRM contact, and nobody retypes the details. AWS describes API integrations as software components that automatically update data between clients and servers, such as a phone's image gallery syncing to the cloud. You can build one with code, a platform or a no-code tool.
The opening sentence is our summary; other definitions come from MDN, IETF and W3C documents, project sites and vendors' developer documentation, read in October 2026.
API, endpoint, request and response in plain words
MDN defines an API (Application Programming Interface) as a set of features and rules inside a software program that lets other software interact with it. MDN adds that an API can be seen as a simple contract between the application offering it and other items. Think of a restaurant menu: it lists what you can order and keeps the kitchen out of sight.
"There are two types of messages: requests sent by the client to trigger an action on the server, and responses, the answer that the server sends in response to a request."
Source: developer.mozilla.org
An endpoint is the address on the other side. AWS describes API endpoints as the final touchpoints in API communication: server URLs, services and other specific digital locations where information is sent and received.
The exchange happens in HTTP messages. In MDN's terms, the client sends a request to trigger an action on the server, and the server sends back a response. Each request names a method:
- GET requests a representation of a resource and should only retrieve data.
- POST submits an entity, often changing state on the server.
- PUT replaces the target resource with the request content.
- PATCH applies partial modifications to a resource.
- DELETE deletes the specified resource.
Every response carries a status code. MDN lists five classes: informational (100-199), successful (200-299), redirection (300-399), client errors (400-499) and server errors (500-599). The message body is commonly JSON. MDN defines it as a data-interchange format for numbers, booleans, strings, null, arrays and objects.
A status in the 200 range, which MDN classes as successful, shows that the server handled the request, not that the result is what you intended. Read the body too, and treat an empty body where you expected data, or an error message inside a 200 response, as a failure. For writes that matter, keep the ID the API returns and read the record back with a GET before the next step relies on it. One user on r/AgentsOfAI found that an AI agent had reported a spreadsheet update that never happened: "the api had just returned a 200 with an empty body and it treated that as success."
How an API integration works, step by step
Take a web form that creates a HubSpot contact and then posts a note to a Slack sales channel.
- Trigger. A visitor submits the form. Either the form tool pushes the entry to your integration at once, or the integration checks for new entries on a schedule.
- Authentication. The integration proves it is allowed to call the CRM. HubSpot's Contacts API requires the crm.objects.contacts.read or crm.objects.contacts.write scope, and creating a contact is a write.
- Mapping fields. The integration matches form fields to CRM properties: email to email, name to first and last name. HubSpot treats the email address as the primary unique identifier, which keeps duplicate contacts out.
- Request. The integration sends a POST request to HubSpot's endpoint for creating one contact, with the mapped values in the body.
- Response. HubSpot answers with a status code. Anything from 200 to 299 means success, and 400 to 499 means a problem in the request.
- Next action. The integration sends a JSON payload with the message text to a Slack incoming webhook URL, and the note appears in the channel.
- Error handling and retries. A 429 Too Many Requests answer means slow down, wait and try again. A client error such as a missing required field will not fix itself on retry, so it goes to a person.
- Logging. Each run records the time, the input, the status code and any error message. If a lead never reaches the CRM, someone can trace what happened.
Logs and error alerts catch failures that announce themselves. A run that stops firing, or one that finishes cleanly on data an upstream change has broken, such as a renamed field or a new date format, raises no error at all. So alert on silence as well, for example when no successful run arrives in its usual window, and check results such as row counts and empty required fields alongside status codes. A post on r/AiAutomations described adding a small notification for each successful run, "so silence itself becomes the alarm."
Webhooks are the push version of step 1. GitHub's documentation explains that they deliver data to your server automatically whenever subscribed events occur, instead of polling an API intermittently to see whether data is available. Our webhook vs API guide compares the two.
Types of APIs and integration styles
API styles differ in how requests are shaped and in who starts the conversation.
| Style | How it works | Typical use |
|---|---|---|
| REST | Resource URLs and HTTP verbs | Payments API (Stripe) |
| GraphQL | One endpoint, typed queries | Requesting exact data needed |
| SOAP | XML messaging protocol | Structured data exchange |
| gRPC | Method calls, Protocol Buffers | Calls across machines |
| Webhooks | Server pushes event data | Events as they happen |
MDN defines REST (Representational State Transfer) as a group of software architecture design constraints for efficient, reliable and scalable distributed systems. MDN also notes that HTTP APIs are sometimes called RESTful even when they do not follow every REST constraint.
The GraphQL project defines GraphQL as a query language for your API and a server-side runtime for executing queries using a type system you define for your data. A GraphQL server operates on a single URL, usually /graphql. On graphql.org, the project describes GraphQL as enabling versionless APIs. Even so, its Learn pages also include lessons on schema versioning and change management.
The W3C SOAP 1.2 Recommendation (27 April 2007) describes SOAP as a lightweight protocol for exchanging structured information in a decentralized, distributed environment, using XML technologies. gRPC's documentation says a client can call a method on a server on a different machine as if it were a local object.
APIs also differ by who may use them. Three of the scope-of-use types AWS lists are private, public and partner APIs. Private APIs are internal to an enterprise and connect its own systems and data. Public ones are open to anyone. Partner APIs are accessible only to authorized external developers in business-to-business partnerships. AWS also lists composite APIs, which combine two or more APIs.
Common integration patterns
Integrations also differ in how data flows.
- One-way sync. Data flows from a source to a destination, such as form leads into a CRM.
- Two-way sync. Changes in either system update the other, such as an e-commerce store and an ERP (enterprise resource planning) system sharing inventory and orders.
- Event-driven. A webhook reports each event as it happens, such as a paid order.
- Scheduled batch. A job runs at set times, such as a nightly export of transactions to a data warehouse.
- Orchestration. One trigger runs several calls in order: create the account, set up billing, send a welcome email.
Two-way sync needs one decision before launch: which system owns each field. Give each customer the same ID in both systems, let only the owning system write a given field, and test one real record end to end, such as an invoice that is partly paid and then refunded. After launch, compare the two systems on a schedule, because drift between them raises no error.
Authentication and security basics
API keys are the simplest credential. OpenAI's quickstart has you create one before you make any calls. Treat a key like a password. Stripe tells developers not to embed secret or restricted API keys in source code or client-side applications.
IETF RFC 6749 (October 2012) defines OAuth 2.0 as a framework that lets a third-party application obtain limited access to an HTTP service. One example is access on behalf of a resource owner, through an approval interaction between that owner and the service. In plain words, the account owner approves the connection. The app, which the RFC calls the client, then receives an access token from the authorization server. Access tokens are credentials used to access protected resources. The client can limit what it asks for with a scope parameter, like HubSpot's separate read and write scopes for contacts.
MDN defines HTTPS as an encrypted version of HTTP that uses TLS to encrypt all communication between a client and a server. Stripe requires all API requests to go over HTTPS. Calls over plain HTTP fail, and so do requests without authentication.
GitHub's REST API allows 60 requests per hour for unauthenticated requests, counted per originating IP address. Requests with a personal access token, or from apps acting for you, count towards a personal limit of 5,000 requests per hour; other credentials differ. If you exceed the primary limit, GitHub returns a 403 or 429 with the x-ratelimit-remaining header at 0. GitHub says not to retry until the time in the x-ratelimit-reset header.
Three risks from the OWASP API Security Top 10 2023 bear directly on integrations. One is Broken Authentication, and the other two name integrations outright. API4:2023 Unrestricted Resource Consumption notes that emails, SMS, phone calls or biometric validation are provided through API integrations and paid for per request. As a result, a successful attack can cause denial of service or higher operational costs. API10:2023 Unsafe Consumption of APIs warns that developers tend to trust data from third-party APIs more than user input. So attackers go after integrated third-party services instead of the target API directly.
Three ways to build an API integration
The main difference is who builds the integration and who keeps it running.
| Approach | Who builds it | How it is paid | Good for |
|---|---|---|---|
| Custom code | Developers or an agency | Developer time or contract | Core or unusual workflows |
| Platform or automation tool | Ops, marketing, analysts | Plan tiers or usage | Internal app-to-app flows |
| Unified API | Your product developers | Per linked account (Merge) | Customer-facing integrations |
Hire API integration developers or a services firm when the integration is part of your product. The same goes for an API that needs unusual authentication or heavy data transformation, and for retry logic that has to be exact under rate limits. A useful brief names the endpoints and the field mapping. It also says how errors and retries are handled, how the integration is tested in a sandbox before launch, who watches the logs and who handles breaking API versions. Custom work is paid as developer time or a project contract. Compare written quotes against one brief.
A platform is enough when your apps already have connectors and the logic fits a handful of steps and branches. The process owners also need to be able to maintain it. An HTTP request step covers apps without a connector.
Larger companies often use an iPaaS (integration platform as a service), cloud middleware with shared connectors, logging and access rules. Any platform spares you point-to-point scripts, one per pair of systems, which multiply with every new app.
A unified API suits software companies that need customer-facing integrations. Merge positions its Unified product as a way to ship them across hundreds of apps through one API. Its pricing page lists six categories: accounting, ATS, CRM, file storage, HR and ticketing.
As of September 2026 the Launch plan has a rate limit of 100 requests a minute and links 3 production Linked Accounts free. Then it costs $650 a month for up to 10, plus $65 for each Linked Account after that. Professional and Enterprise are sold on contract. Merge meters production Linked Accounts rather than API calls. Merge defines a Linked Account as an end user's connection between your app and a third-party platform. Its pricing page does not say whether an account is counted monthly-active or once ever, or whether unlinking an account stops the charge. Confirm how yours will be counted.
API integration examples
- Taking payments. Stripe's API is organized around REST. It takes form-encoded request bodies and returns JSON-encoded responses, so a checkout or invoicing tool can create payments over HTTPS.
- Syncing contacts with a CRM. HubSpot's Contacts API creates and manages contact records and syncs contact data between HubSpot and other systems. The email address is the identifier that prevents duplicates.
- Posting to Slack. Creating an incoming webhook gives an app a unique URL. The app sends a JSON payload with the message text and options, and the message appears in Slack.
- Calling an AI model. OpenAI's quickstart presents its API as a consistent interface to AI models for text generation, natural language processing, computer vision and more. You reach it with an API key.
- Geocoding addresses. Google's Geocoding API accepts an address, latitude and longitude coordinates or a Place ID, and converts an address into coordinates and a Place ID.
Common problems and how teams handle them
- Rate limits and HTTP 429. MDN describes 429 Too Many Requests as a user sending too many requests in a given amount of time. Stripe recommends exponential backoff: retry after longer and longer waits.
- Pagination. Stripe's list methods use cursor-based pagination and return between 1 and 100 objects per request, with a default of 10. An integration that reads only the first page never sees the rest.
- Versioning and deprecations. Stripe releases new API versions monthly with no breaking changes. Twice a year it ships a major release, which starts with a version containing breaking changes. In October 2026 its reference showed 2026-09-30.endive. Pin a version and test against the new one before upgrading.
- Timeouts and retries. When a connection drops, you cannot tell whether the request landed. Stripe's idempotency keys let you repeat a request without creating a second object. Keys can be up to 255 characters. They are accepted on all POST requests and have no effect on GET and DELETE. A key becomes eligible for removal once it is at least 24 hours old, so reusing it after pruning creates a new request.
- Schema changes. Fields get renamed or added. Validate what comes back instead of trusting it. OWASP's API10 makes the same point about third-party data.
- Monitoring. Log status codes and alert on repeated failures. Every Stripe request has an identifier in the Request-Id response header. Stripe asks for it when you contact support, so store it.
"If you exceed your primary rate limit, you will receive a 403 or 429 response, and the x-ratelimit-remaining header will be 0. You should not retry your request until after the time specified by the x-ratelimit-reset header."
Source: docs.github.com
Two habits keep a retry after a timeout from doing the work twice. With Stripe, create one idempotency key per operation and send that same key with every retry of that operation. Where an API offers no such key, record a timed-out write as unknown rather than failed, and check whether the record already exists before you send it again.
Building an API integration without code
No-code and low-code platforms offer ready connectors, a visual canvas and point-and-click field mapping. When an app has no connector, use an HTTP request step. Make's HTTP app has a Make a request module that sends an HTTP request to any server, over HTTPS only. According to Zapier's help center, Webhooks by Zapier and API by Zapier work as HTTP request steps for apps without a Zapier integration. To start a workflow from another app, use a webhook trigger. Zapier's Catch Hook gives a unique URL for this on paid plans, not Free, as of October 2026.
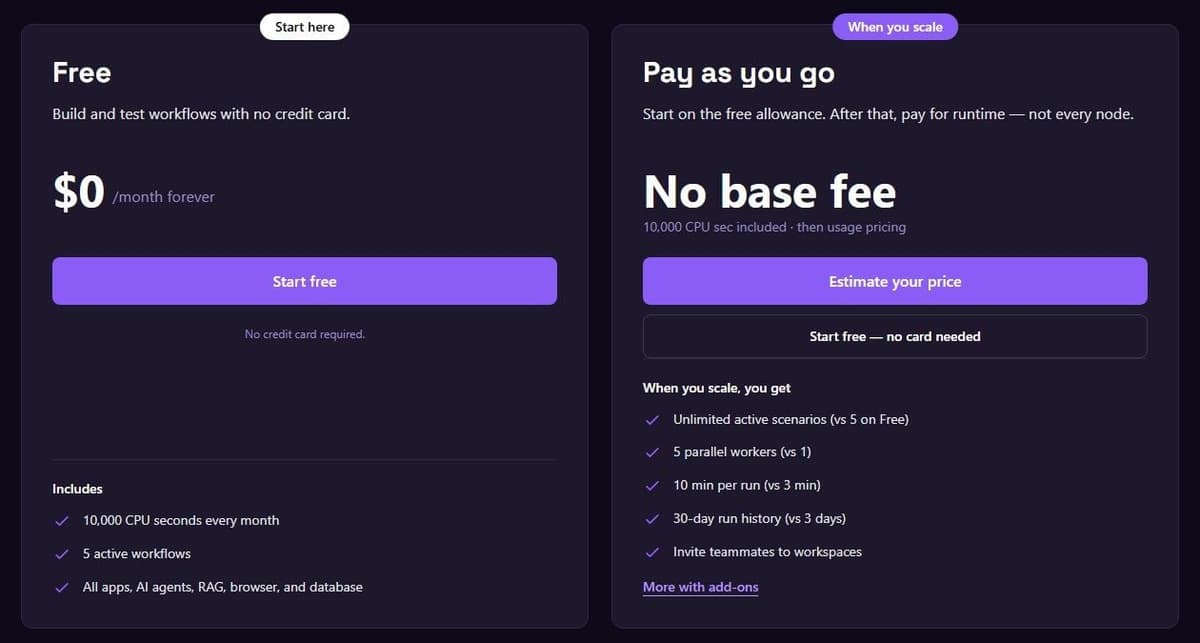
Latenode, which publishes this blog, has a visual drag-and-drop builder, webhook triggers, custom JavaScript nodes and a headless browser for sites without an API. As of September 2026 it bills workflow runtime in CPU seconds (runs times average seconds), and the first 10,000 CPU seconds each month are free. Billing is not per operation or per step, so adding steps does not multiply the bill. Nodes that call paid external providers are billed on top, at $1 per PnP token of actual provider usage. Cost depends on run duration, which means it is not directly comparable to other platforms' tasks, operations or credits.
Benefits of API integration
The first benefit is less manual data entry and fewer copying mistakes.
- One version of each record. Synced CRM and billing tools show sales and finance the same customer details.
- Faster reactions. Webhooks deliver events in near real time, not at the next nightly export.
- Reuse. A store can use a payments API instead of building payment processing itself.
- Longer life for legacy systems. An older system with an API can feed new cloud apps.
API integrations also hold up better than screen automation. MDN likens an API to a contract, and Stripe, for example, saves breaking changes for a major release twice a year, while a bot that clicks through web pages depends on a layout that can change any day. Keep browser automation, headless browser steps included, for sites with no API. A post on r/AI_Agents described where screen-driven agents fail: "It holds together right up until someone moves a button, renames a field, or adds a modal."
The price is upkeep: each integration needs an owner who reads its logs and retests it after API version changes.
Give that owner the accounts as well. Connect each integration through a shared service account rather than one employee's login: OAuth access is often granted on behalf of the person who approved it, and that person may leave. Sign up for vendor developer accounts with a team email address too, so deprecation notices reach someone. One user on r/automation put it this way: "credentials expire, schemas drift, retries create duplicates, and nobody knows whether the client or developer owns the fix."