
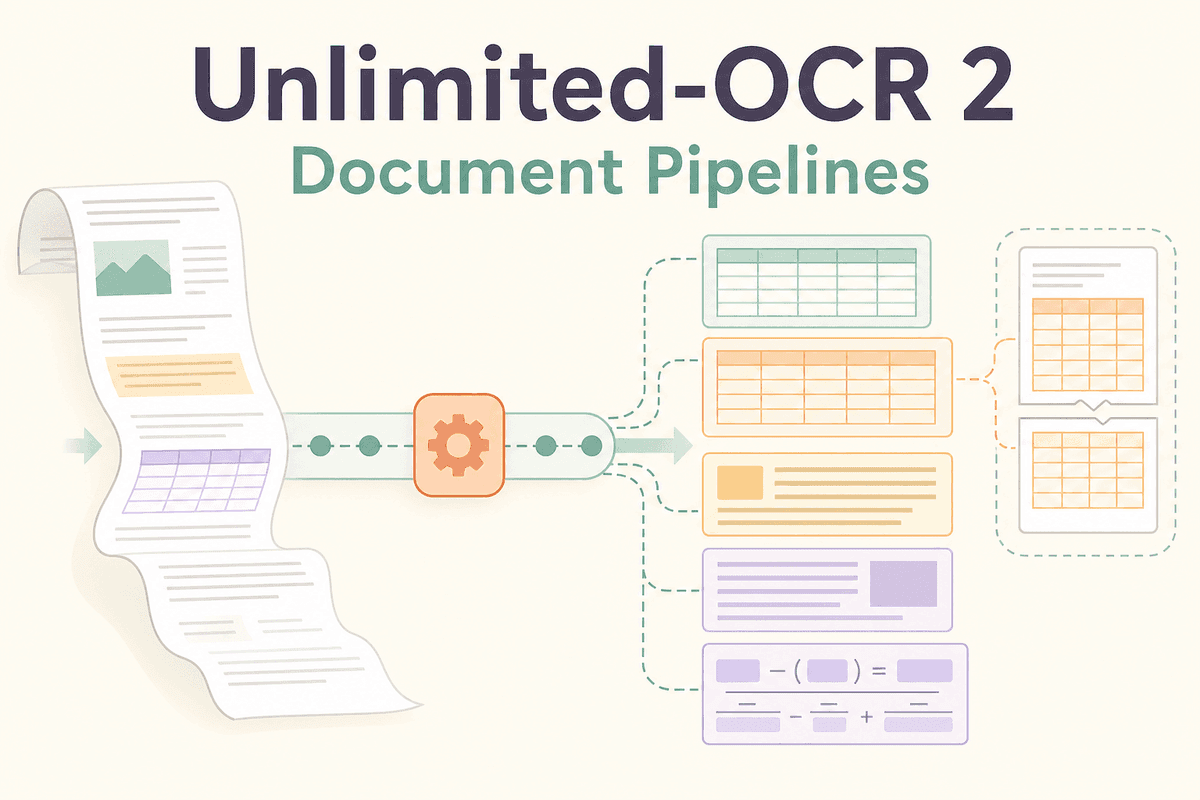
On October 27, 2026, Baidu updated its cloud document parser to use Unlimited-OCR 2, making the long-document model available as a hosted OCR API rather than something teams need to deploy themselves.
According to the Baidu Cloud OCR documentation, the service supports PDFs up to 500 pages and can return parsed output as structured JSON or Markdown. Baidu says it is built for structure-heavy files, including cross-page table merging, paragraph continuation across pages, title hierarchy parsing, and layout tagging for elements such as tables and equations.
The API uses an async flow rather than a single blocking request. A client submits a file or URL, receives a task ID, and then polls for completion before fetching result links. That makes it easier to fit into automation workflows that already separate ingestion from downstream extraction or review.
On the model side, Baidu says Unlimited-OCR 2 uses SR-SWA to keep decoding latency and memory footprint nearly constant as document length grows; more detail is on the model page. For builders, the practical change is access: long-PDF parsing is now exposed through Baidu Cloud’s managed API.