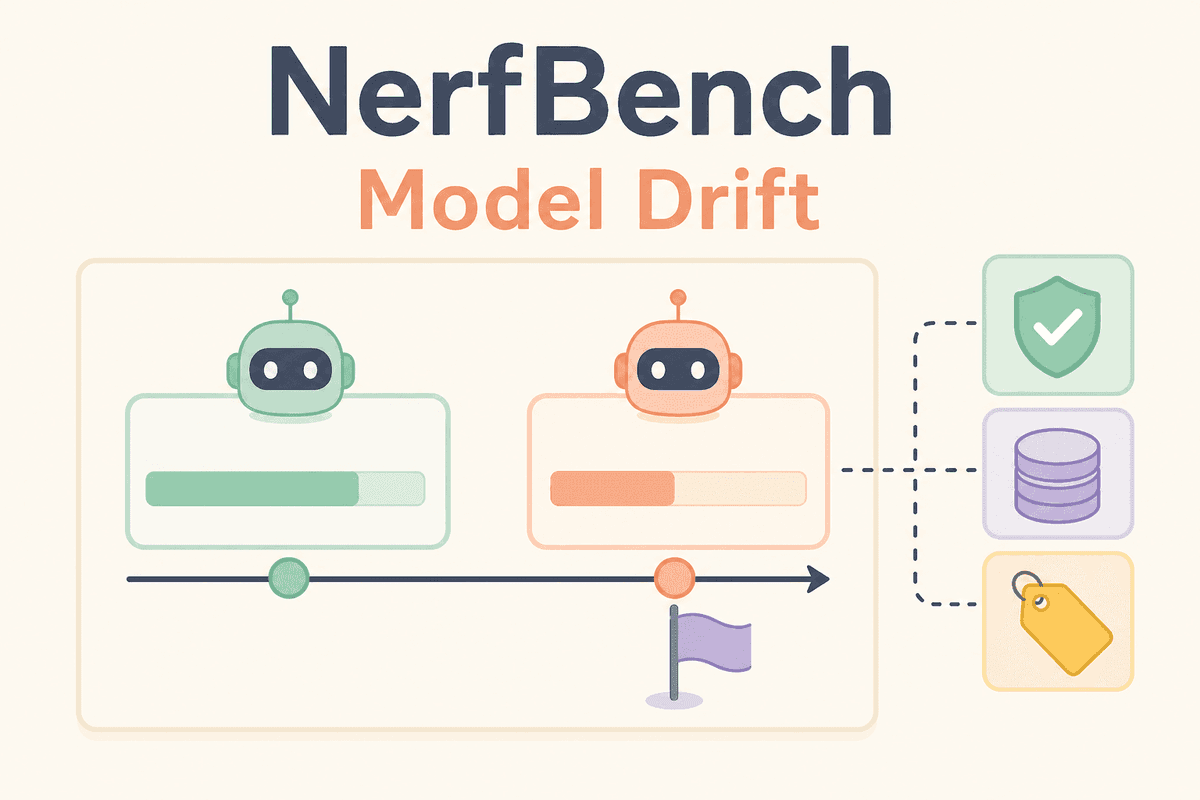
On September 27, 2026, Bridgebench announced NerfBench, a benchmarking project aimed at checking whether models change after release in ways that affect quality or cost. According to Bridgebench, each model gets a launch-day benchmark that becomes its 100% reference score, and later retests measure performance alongside tokens used and cost per task.
Bridgebench says scores between 90% and 110% count as normal variance, while results below 90% are flagged for possible degradation. The project also said it pledged $10,000 to track whether AI labs "nerf" models after launch.
The setup does not by itself show intent, but it gives teams a repeatable way to separate anecdotal complaints from measured regression checks across quality, token use, and unit cost.