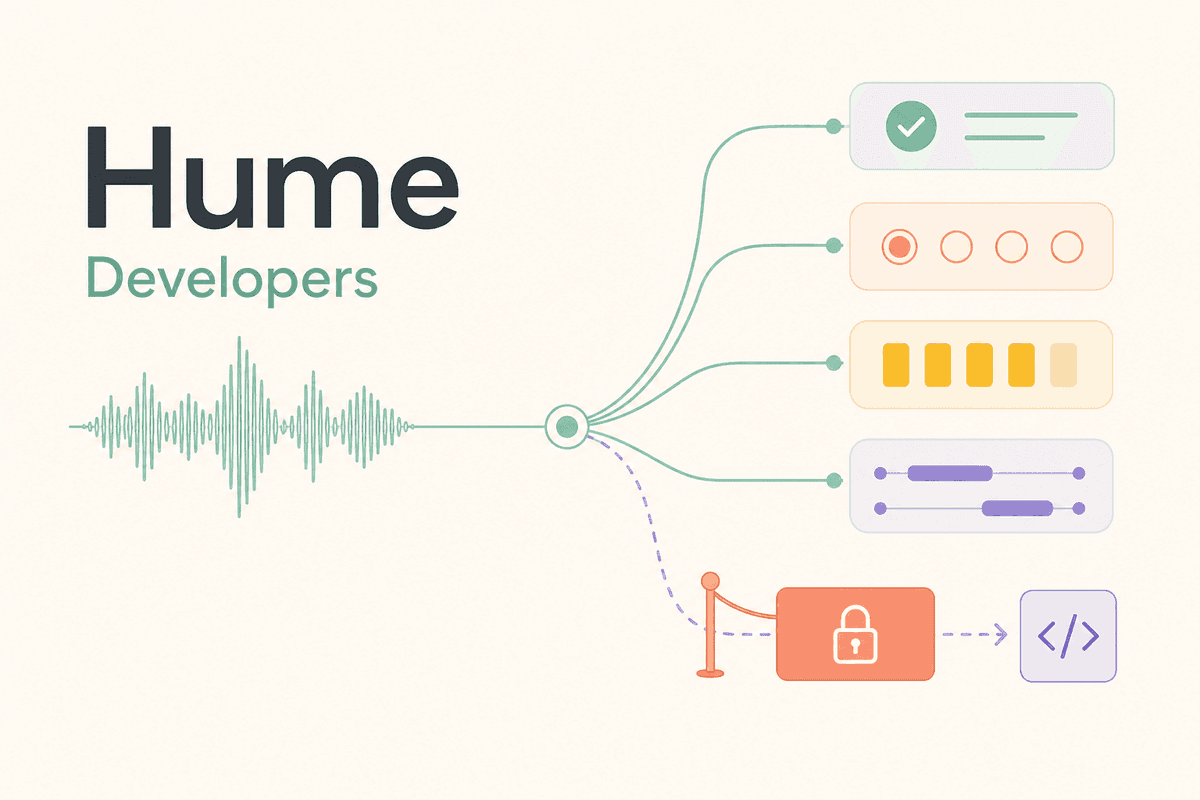
On November 2, Hume introduced an Audio Decision API that lets developers ask structured questions about speech and other sounds in raw audio, with access currently limited to a waitlist. A playground is also available for testing, according to the Hume announcement.
Rather than stopping at transcription, the API can return decision-style outputs including yes/no answers, multiple-choice selections, rating scales, and timestamped spans. Hume’s use-case documentation shows examples such as counting distinct speakers in a clip and marking where laughter occurs.
For builders, that creates a way to route automations from audio itself instead of text alone. A workflow could branch on speaker count, overlap, laughter, or perceived frustration before any transcript is parsed. Hume also describes these outputs as estimates of human judgment, so teams would still need to validate thresholds on their own recordings before using them for high-stakes actions.