
DFlash 2: a 3.43× drafter that fades to 1.45× under load
Published September 22, 2026
A drafter that guesses the whole block at once
Speculative decoding has the same shape everywhere: a small model proposes tokens, the big model checks them in one pass, and you keep whatever survived. The proposal step has stayed autoregressive — one token, then the next. DFlash 2 makes it a single pass:
the entire block, every position, predicted in parallel.
— Inco AI
A lightweight selector then traces one coherent path through the candidates it kept at each position, and two-tap dynamic convolutions stop the draft degrading toward the end of the block. The vendor prices the whole arrangement at over 20% more output per verification pass for around 1% of added cycle latency. The convolutions are the cheap part of that: they add 0.7% to the draft–verify cycle, where the ten extra Transformer layers that would buy comparable accuracy add 15.2%.
None of this is supposed to change what the model says:
Decoding is lossless: greedy output matches the target model exactly, and sampling preserves its distribution.
So the pitch is clean. Same text, fewer seconds. The question is how many fewer, and under what load.
Five weeks old, and only now worth arguing about
Nothing here shipped this week. Inco AI released two DFlash 2 drafters on 18 August, one for Qwen3.8-27B and one for Muse Glimmer, and the number it led with was a single-request number:
SGLang serves at 2.7–3.4× the throughput of autoregressive decoding at batch size 1
— Inco AI
The drafter entered our feed on 17 September, which is a fact about the feed and not about the project. What has changed is the interval. The vLLM implementation of the method merged on 21 August — the model card's quick start still tells you to install from that pull request, #52816, which dates the card rather than the ecosystem. And a drafter trained for Qwen3.8-27B could not be stress-tested before the drafter existed, so every load measurement anyone has, including the concurrency-8 reproduction further down, postdates the release.
One thing the vendor did at release deserves naming. It published the concurrency-8 and concurrency-32 tables itself, on the model card, directly under the headline. Most vendors would not have. That is why the disagreement is about how to read the numbers rather than about whether the numbers exist.
The disagreement starts in the vendor's own tables
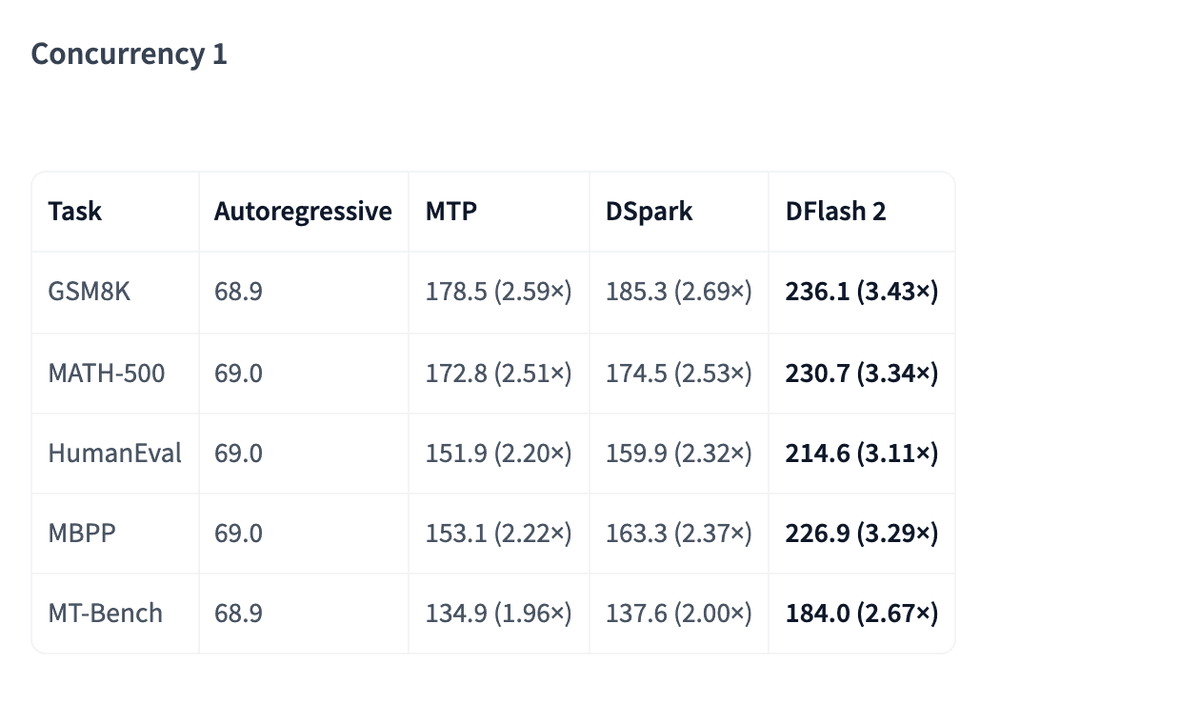
Every figure on the model card comes from one configuration: SGLang on a single NVIDIA H200, FlashAttention 3 for both target and draft attention, speculation block size 8. Under it, the GSM8K curve reads 3.43× at concurrency 1, 2.84× at concurrency 8, and 1.45× at concurrency 32.
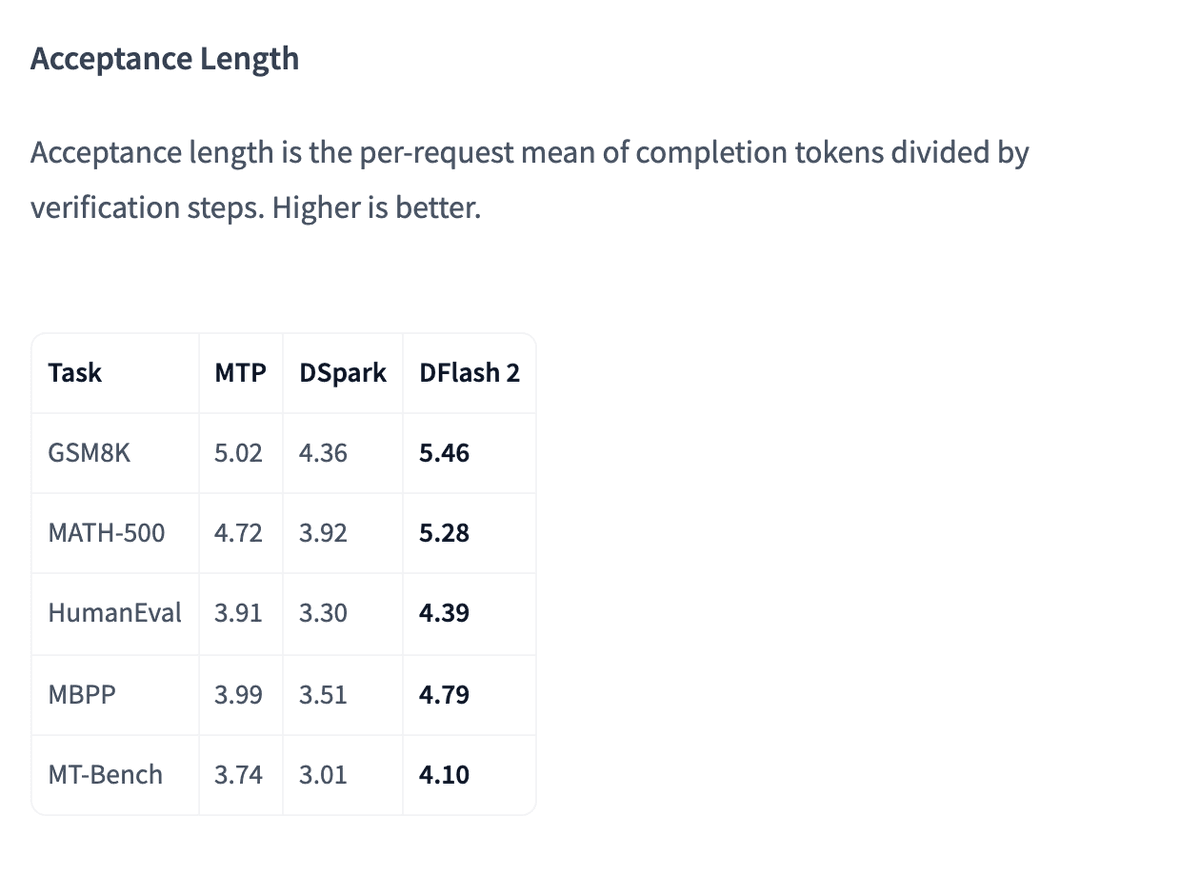
Task type moves the result almost as much as load does, and the reason is in the table at the top of this page. Acceptance length — completion tokens divided by verification steps — runs 5.46 on GSM8K and 4.10 on MT-Bench. Fewer drafted tokens survive each verification step on open-ended chat, so there is less to win; MT-Bench duly ends at 1.01× where GSM8K holds 1.45×.
The decay across load has a separate cause, and it is not a bug. Producing one token moves far more weight data than it does arithmetic, so a GPU's multipliers are mostly unoccupied while it happens. Speculation is one way to spend that unoccupied capacity. Batching is another, and there is only one pool.
The batch and the draft are drawing on the same account.
That measurement was taken on AMD RDNA4, not on an H200, and the arithmetic is specific to it: per-agent draft capacity of (24 − batch_size) / batch_size, which is about 23 tokens of speculation for a single agent and about 2 each once eight are running. Different silicon, same shape — and the shape is the one the model card's own tables trace.
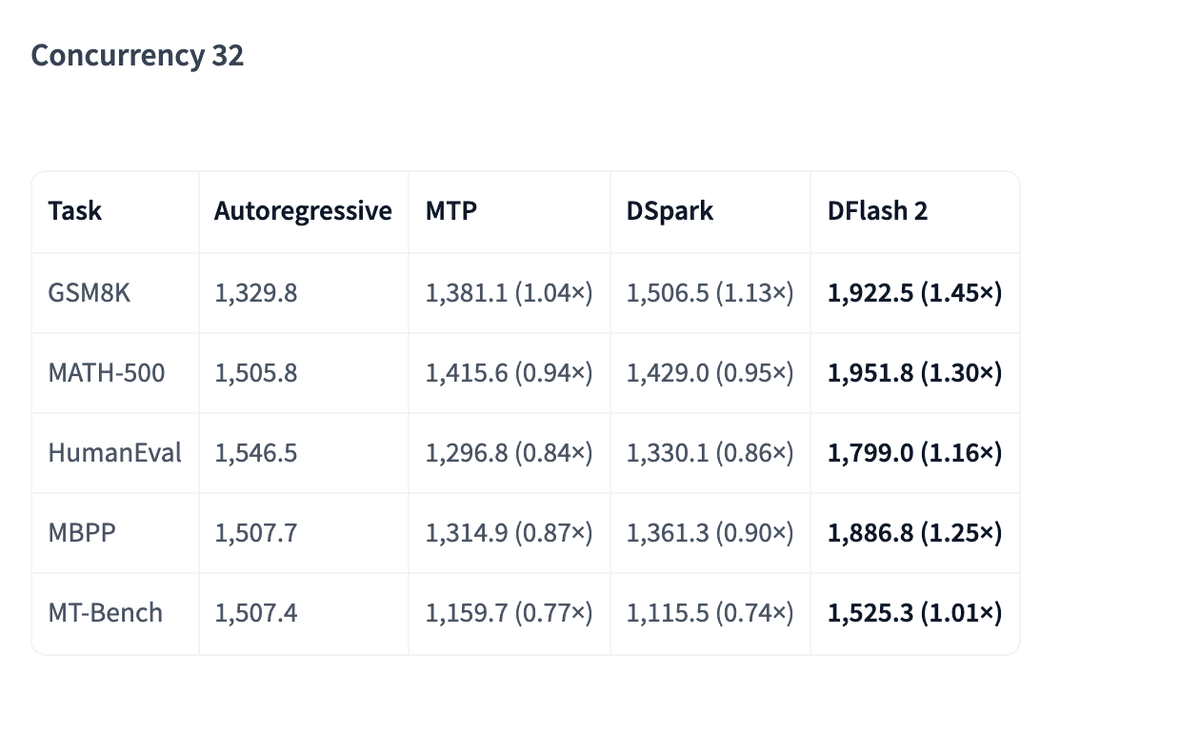
Look at what happens to the neighbours in that frame. At concurrency 32, MTP and DSpark read below 1.00× on MATH-500, HumanEval, MBPP and MT-Bench. Speculation is not merely failing to help there; it is taking throughput away. DFlash 2 stays above water on all five tasks, which is a real result — it just is not the result anyone quotes.
The failure mode this produces in practice is a planning failure, not a technical one:
sees 2.5x speedup, ships it — then observes 5% regressions in production where p50 concurrency is 16
— Tian Pan
Second cost, and this one is a correctness problem rather than a performance one. Running the cookbook configuration for DFlash 2 with Qwen3.8-27B on SGLang:
under high concurrent load, sometimes the last user message is appended to the wrong context
L3tum was on an RTX Pro 6000. What makes the report hard to wave away is that a second person reproduced it on different hardware and then measured it: gabrielbryk, on a DGX Spark against an NVFP4 target, logged 7 wrong answers in 100 requests at concurrency 8, against 0 in 100 running the same configuration serially and 0 in 304 with speculation switched off. Expanding the affected cases into a larger sample put the failure rate within that subset at 111 of 304 — the figure people quote, and not the rate your traffic would see. Inside that expanded set, switching the target to a dense BF16 lm_head cut 111 failures to 1 and did not eliminate them, which argues the drift is in the verification path under batch composition rather than in a quantisation artefact. These are not crashes. They are well-formed completions that restate the constraints correctly and then answer a different question. Reverting to MTP made them stop. No fix is published.
Third, memory. The model card states 2B parameters in BF16 for the drafter and never converts that to gigabytes or to a share of the H200's pool.
Spec decode isn't free. You're paying VRAM for both models simultaneously.
That write-up was about a 4B draft model, not DFlash 2, and the transferable part is the accounting rather than the figures: both models sit in memory at once, the serving stack pre-allocates more than you estimated, and the two fixes on offer are shrinking the draft model or cutting parallelism. Dropping to a 0.6B draft recovered about 2 GiB there. Both moves shrink the speedup you were buying.
In the vendor's defence: it published the decay, it published a definition of acceptance length you can check its tables against, and it was straight about how the comparison was built.
We trained the DFlash and DSpark drafters ourselves under matched setups, while MTP ships with the model.
— Inco AI
Read that twice. It is a disclosure of good practice and a warning at the same time: two of the three baselines DFlash 2 beats are the vendor's own reimplementations.
Where the concurrency question reappears
Most people reading this will never own the GPU the drafter runs on. What they own is the orchestration in front of it, and for them the whole question collapses into one number: wall-clock time on their own prompts at their own concurrency. That is a thing you can build in an afternoon. Take the twenty or thirty prompts your product actually sends, put them in a Latenode workflow that calls two endpoints from a catalogue of roughly 335 models, and let a JavaScript node — which can install any NPM library — time each call and log the pair. Then stop running it one at a time. Fire the workflow in parallel to reproduce the load you serve: a paid plan includes 5 parallel execution workers, and more are an add-on at $10 per worker per month, so the concurrency in your test is a number you chose and can quote next to the result, which is exactly what the vendor tables do and what most internal benchmarks do not. The meter cooperates with the experiment — Latenode charges for the CPU-seconds a run actually consumes, not per node and not per API call, with no per-execution minimum, so a sweep of a few hundred short runs costs the seconds it takes rather than a flat fee per run. There is no DFlash 2 or SGLang integration in Latenode and this article is not claiming one; decoder speed stays the provider's problem. The transferable part is the measurement, taken under your load rather than the benchmark's.
Who should spend the afternoon
Run it if your workload genuinely looks like the benchmark: long generations, few requests in flight, an H200-class card, a target in the Qwen3.8 family, and SGLang or a vLLM new enough to carry the August merge. Batch document processing overnight, a single-developer coding assistant, an internal agent that nobody else is queueing behind. In that regime the acceptance lengths are the best of the three drafters on every task measured, and 3.43× is real.
Do not run it in a shared serving tier this quarter. Two reasons, and the second is the disqualifying one. The throughput case thins out exactly where production lives:
Above that, the gains from speculation are consumed by verification overhead at scale.
— Tian Pan
And seven requests in a hundred returning a confident wrong answer at concurrency 8, where the same configuration with speculation off returns none, is not a tuning parameter. Until that issue closes, the honest position is that DFlash 2 is a good drafter with an unresolved integration bug in the stack its own cookbook tells you to run it on.
If you are evaluating anyway, measure two things the card does not give you: resident memory with the drafter loaded and your real KV-cache settings, and answer accuracy at your p50 concurrency rather than at one. Both are cheap. Both are the numbers that decide it.
This is how things stood on September 22, 2026. Projects move fast — check the source before you rely on it.
Questions people ask
- What else, besides the H200, do the published numbers depend on?
The block size is 8, meaning seven draft tokens per verification step; sampling follows Qwen3.8's recommended temperature 1.0, top-p 0.95, top-k 20; and output is capped at 4,096 tokens. Every throughput and acceptance-length figure on the card was produced under that exact combination, so a deployment that differs on any of them is not comparable until you re-measure it.
- Can I run it on vLLM?
The vLLM implementation merged on 21 August 2026, so the method exists upstream there as well as in SGLang. The card has not caught up: its quick start still tells you to install from pull request #52816, which was still unmerged when the card went up. Check your vLLM version against the merge rather than following the card. Note also that the concurrency-8 correctness reports were filed against SGLang, which means vLLM's behaviour under the same load is unmeasured in public rather than clean.
- Does DFlash 2 only work with Qwen3.8-27B?
A DFlash 2 drafter is trained against one target, and two were released: this one and a drafter for Muse Glimmer, where the vendor reports 3.1–4.6× rather than 2.7–3.4×. The August release covered those two targets and no others, and the vendor's published measurements cover only the H200. Pairing the drafter with a target it was not trained against is not a configuration option.
- Is the output really identical to the base model?
That is the mathematical claim, and the maths itself is not in dispute: greedy decoding matches the target exactly and sampling preserves its distribution. Whether the implementations honour it is open. The wrong answers at concurrency 8 look like a serving-integration failure, verification-path divergence under batch composition — but the person who measured them points at a second report, z-lab/dflash issue 159, of greedy divergence from plain autoregressive decoding in MLX with no SGLang involved, and allows that some of this may sit in the verification contract itself. Either way the distinction matters to the people fixing it and not at all to the people receiving the wrong answer.
- Why do people report acceptance lengths far below the card's 5.46?
Because acceptance length is a property of the whole deployment, not of the drafter alone. An open report on the DFlash tracker, z-lab/dflash issue 170, has roughly 3 on llama.cpp against roughly 5.5 on vLLM — but the runtime is not the only thing that differs. The targets are different checkpoints, a Q6_K GGUF against an AWQ MXFP4 build, and the two drafters are different quantisations as well. The reporter's leading hypothesis, stated in the issue title, is the target pairing rather than the engine. Control for the checkpoints before you blame the runtime, and read 5.46 as a figure produced by one configuration rather than a target your deployment has failed to hit.