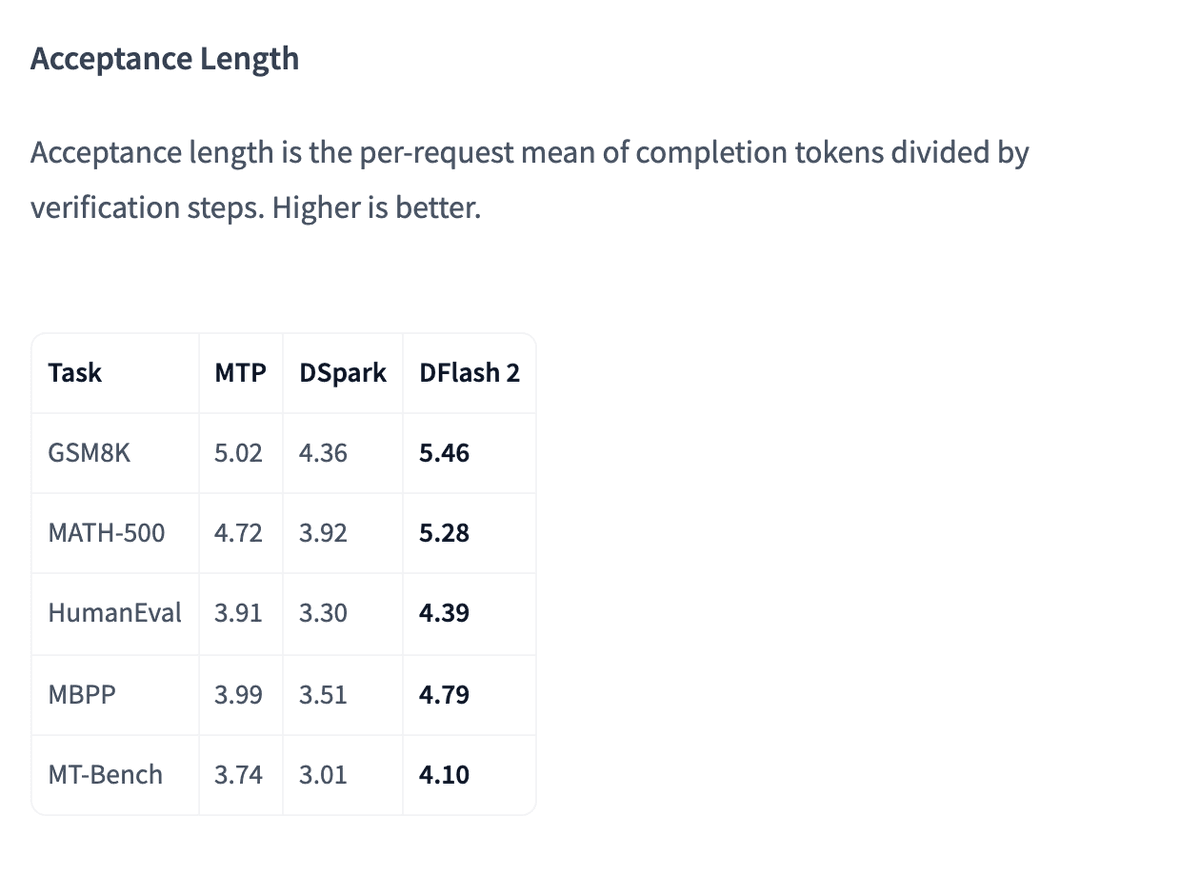
DFlash 2: a 3.43× drafter that fades to 1.45× under load
Inco AI's block-diffusion drafter reaches 3.43× on GSM8K with one request in flight and 1.45× at concurrency 32. Here is what you pay in memory and variance.

Every breakdown we have published, newest first.
Inco AI's block-diffusion drafter reaches 3.43× on GSM8K with one request in flight and 1.45× at concurrency 32. Here is what you pay in memory and variance.
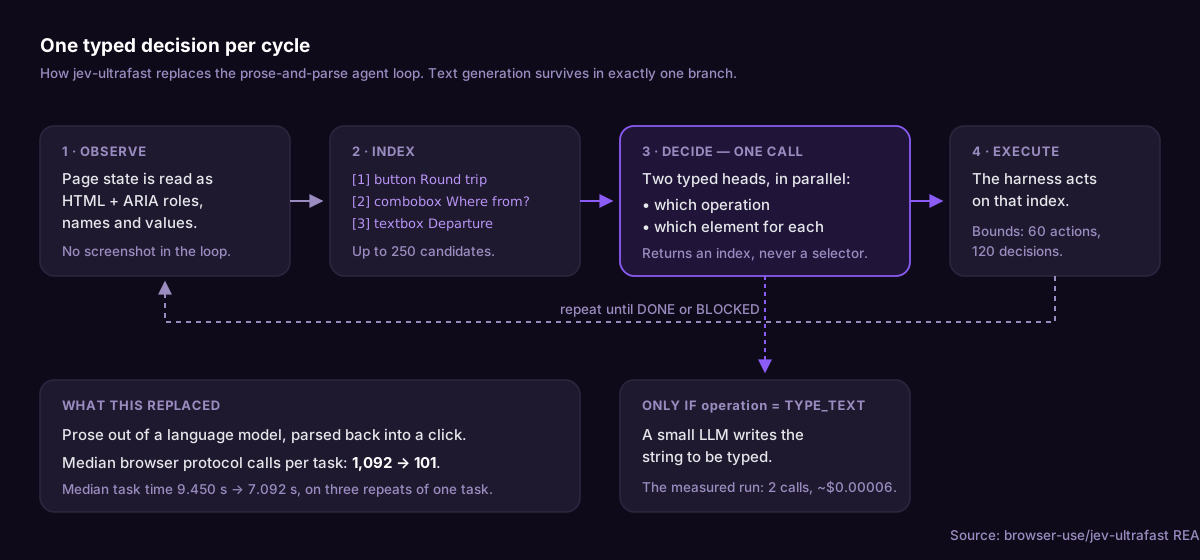
browser-use's jev-ultrafast finishes a Google Flights search in 7.1 seconds by replacing the agent loop with one typed decision per cycle. Here is the catch.
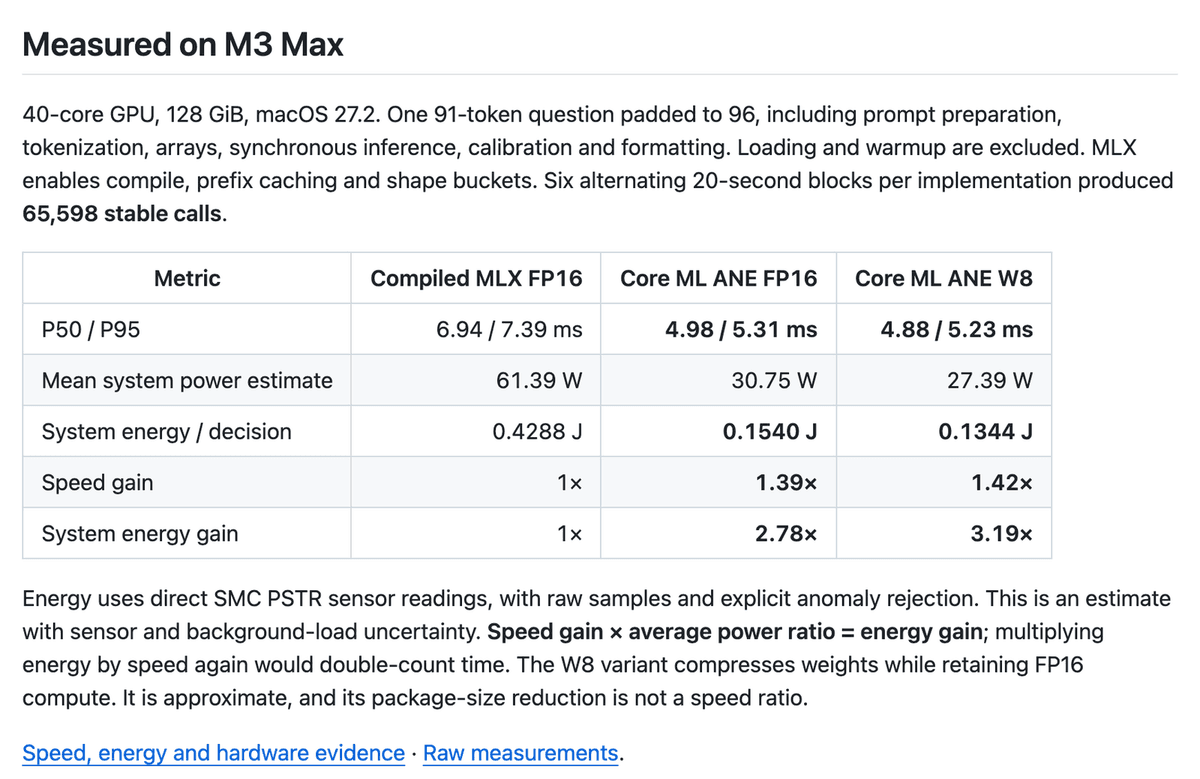
mizorewww's Core ML port runs one Laya typed decision in 4.98 ms and 0.154 J on an M3 Max. What the parity fixtures prove, and what they do not.
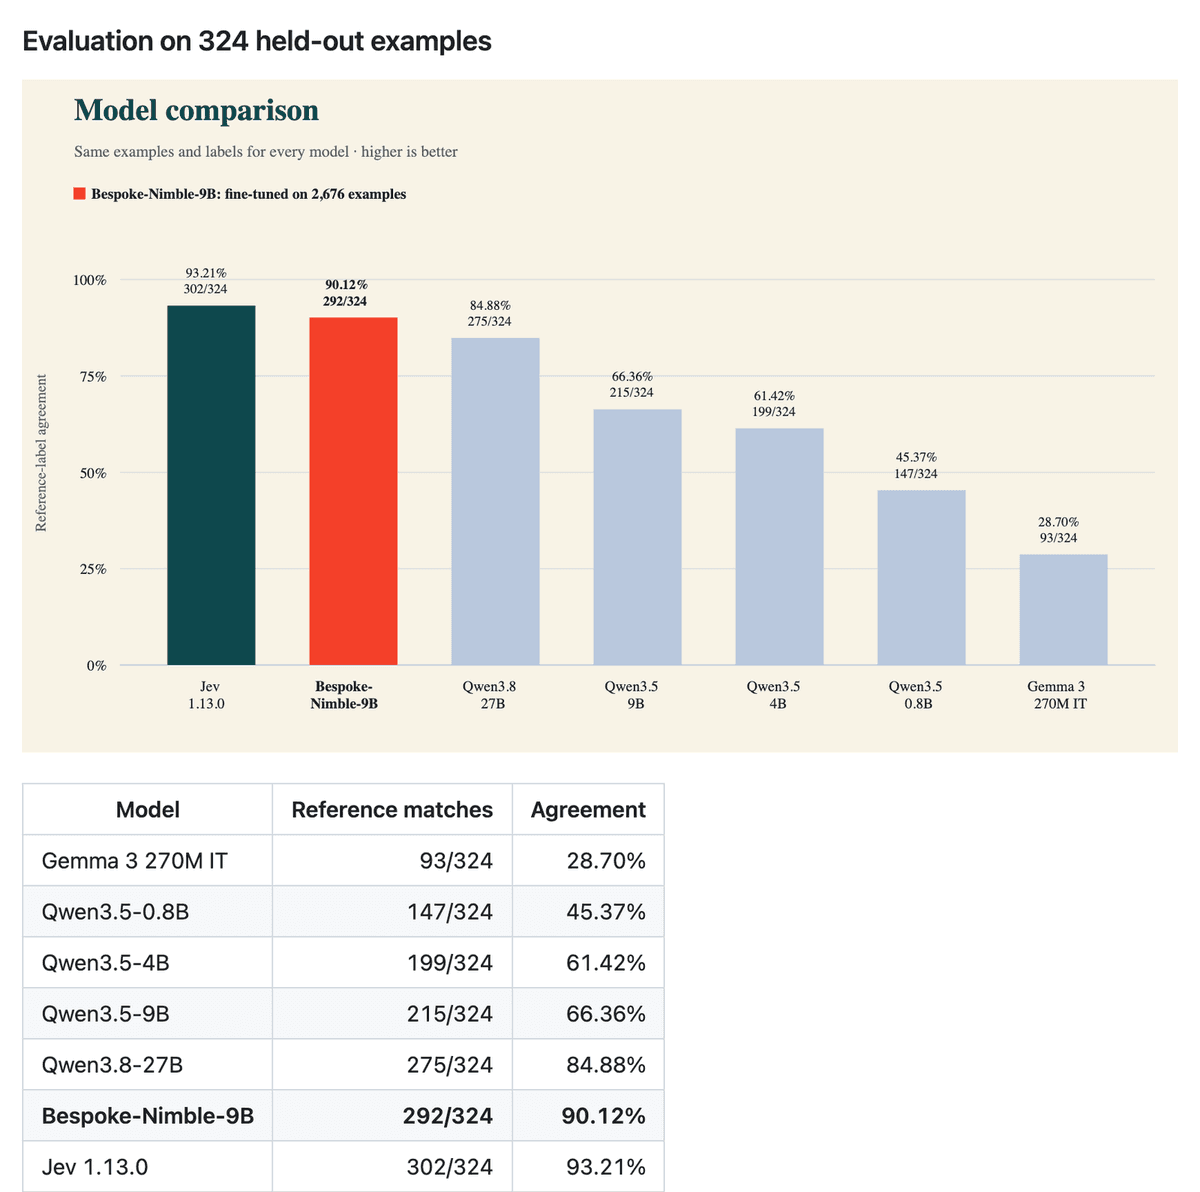
Bespoke Labs fine-tuned Qwen3.5-9B on 2,676 synthetic examples. It reaches 90.12% against Jev's 93.21%, and its evaluation covers six of ten trained domains.