
Jev Ultrafast: the browser agent that stopped writing text
Published September 22, 2026
A browser agent with the generation taken out
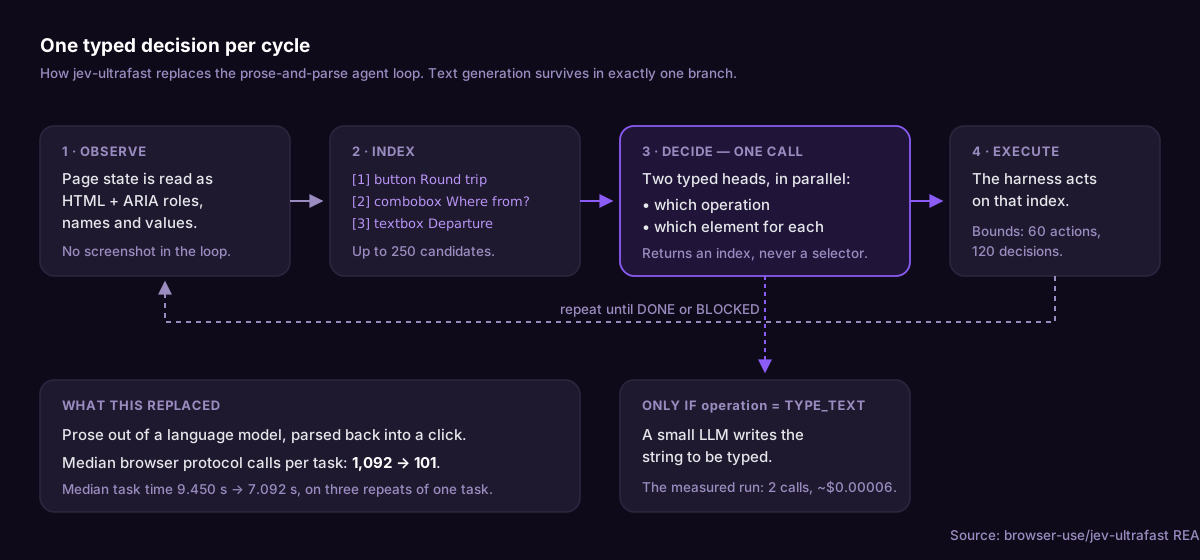
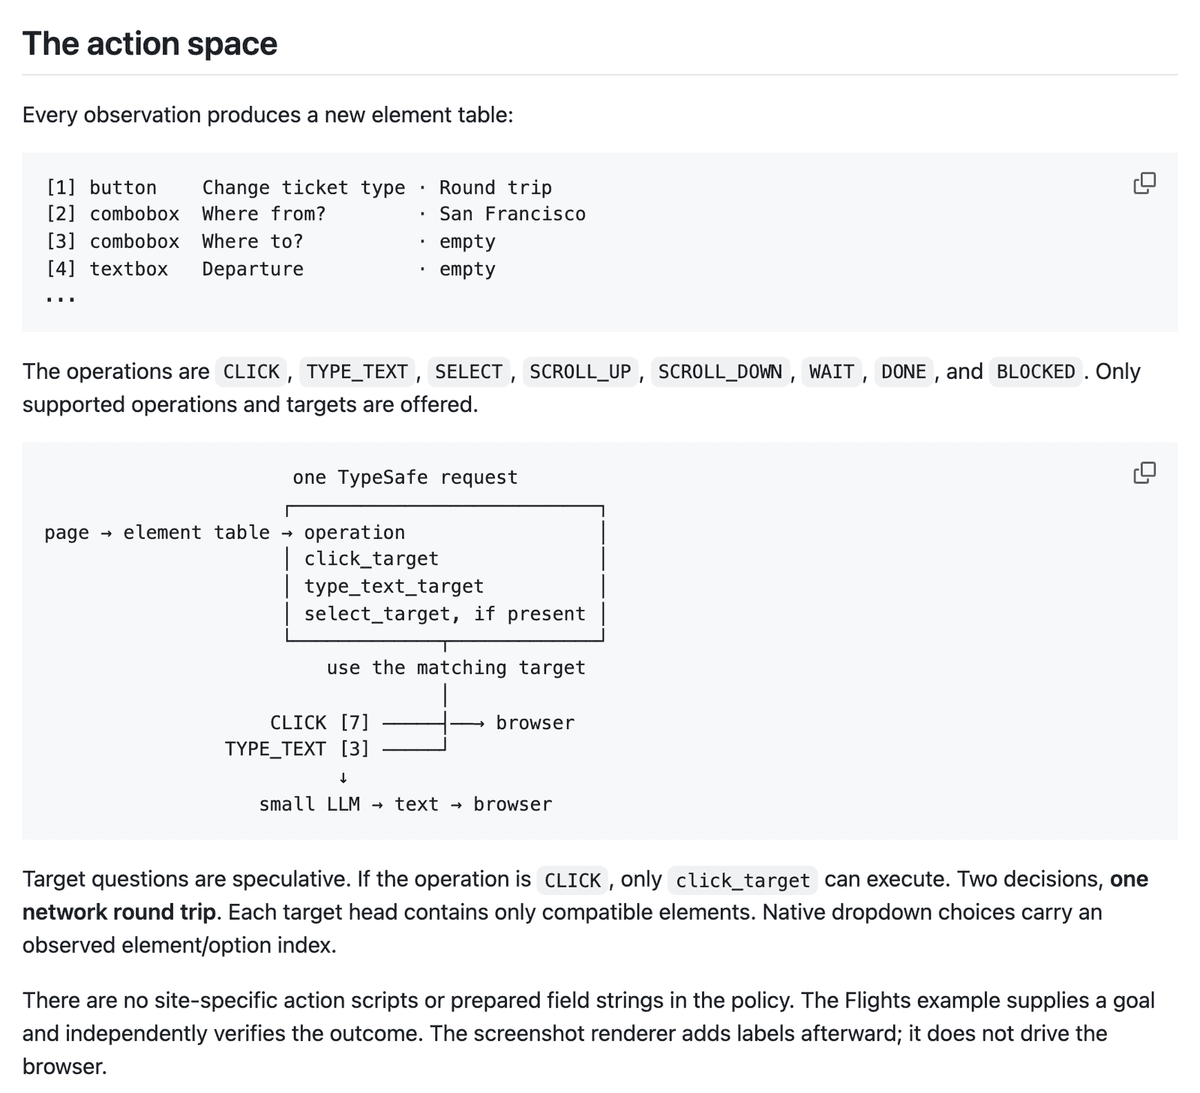
Most browser agents work by asking a language model, in prose, what to do next, then parsing the prose back into a click. browser-use/jev-ultrafast does not. On every observation it builds an indexed table of the page's accessible elements, then asks TypeSafe's Jev model two typed questions at once: which operation, and which element for each operation on offer.
One request per decision cycle. Operation and target heads share the same observed state.
— browser-use/jev-ultrafast README
The operation vocabulary is eight items long: CLICK, TYPE_TEXT, SELECT, SCROLL_UP, SCROLL_DOWN, WAIT, DONE, BLOCKED. Only the operations a given page state supports are offered. Nothing the model returns ever becomes a selector, a coordinate, or executable JavaScript — it returns an index into a table the harness built.
Language generation survives in exactly one place:
A small LLM writes text only when the operation is TYPE_TEXT.
— browser-use/jev-ultrafast README
That is the whole design. A fast classifier decides, a small model types, and a deterministic executor validates the target — document freshness, geometry, click occlusion — before it touches anything.
Why it surfaced this week
TypeSafe opened Jev to the public on 20 September, five days after announcing it. jev-ultrafast was the most visible thing anyone had built on it: roughly 17,000 stars inside a week, and the token jev turning up in 74 separate item names in the same seven-day feed. This is not one project trending. It is an ecosystem forming around a model that shipped with an unusual pitch:
Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.
The agent is the demonstration that the pitch survives contact with something messy. Its own measurement file reports a Zürich to London search on Google Flights finished in 7.1 seconds end to end, including page loads and the text the model typed into the fields. Against the project's previous architecture:
Median task time went from 9.450 s → 7.092 s, a 25% reduction; median browser protocol calls went from 1,092 → 101.
— browser-use/jev-ultrafast README
The 25% is the headline. The tenfold drop in browser protocol calls is the interesting number, because that is the part that scales: fewer round trips per decision means the cost of running a hundred sessions in parallel falls with it.
What people are actually arguing about
Nobody has published a critique of this agent. It entered this week's feed on 16 September, has one contributor, no published releases and commits five days old, and the only public measurements of it are its own. The honest thing to report is that the disagreement is one layer down, about the model the agent is built on — and that most of it transfers.
The project is unusually straight about the limits of its own numbers:
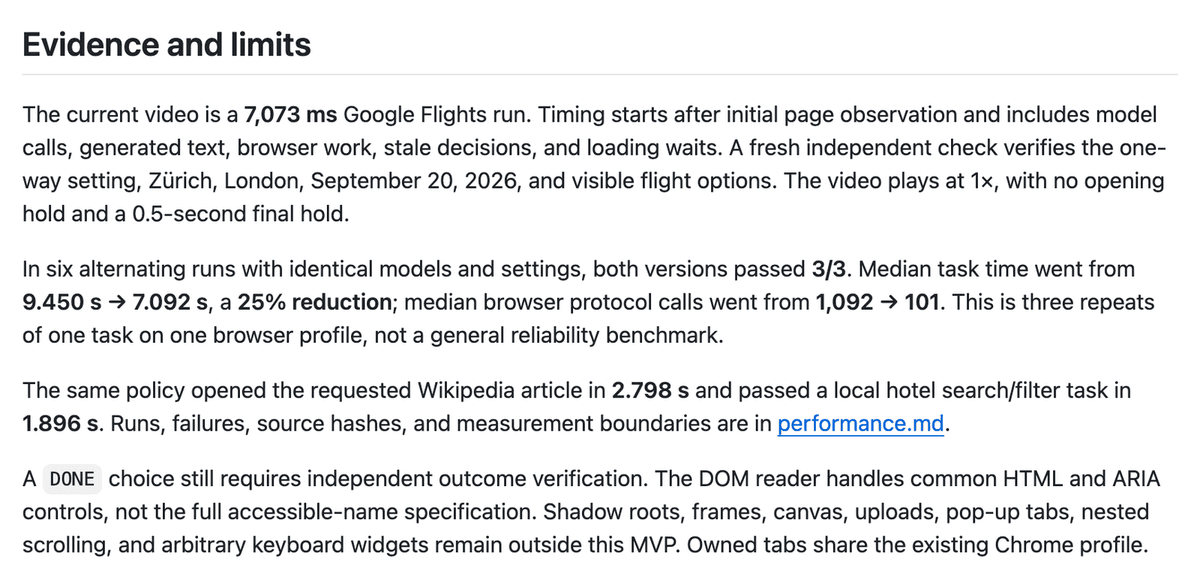
This is three repeats of one task on one browser profile, not a general reliability benchmark.
— browser-use/jev-ultrafast README
TypeSafe's announcement makes a strong claim for the architecture: because Jev gives up string generation entirely and returns a value from a schema, it cannot hallucinate. The vendor's own charts put that at zero on both of its error measures:
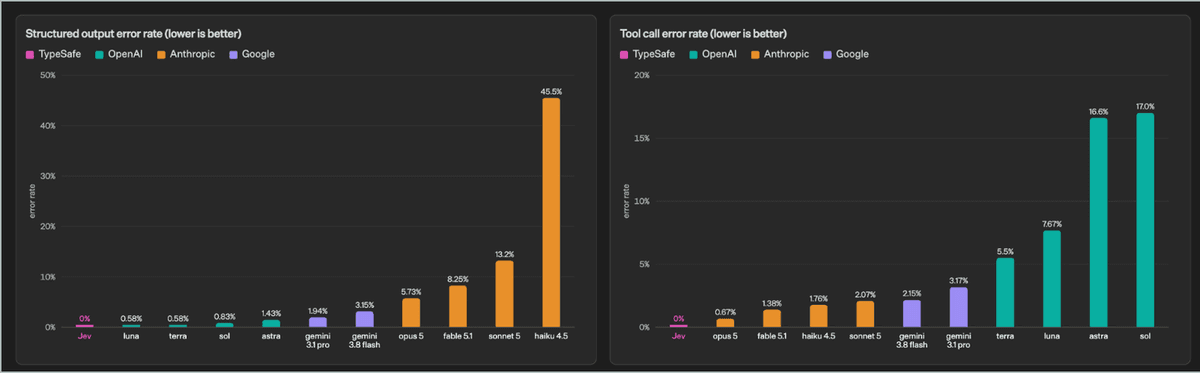
The sharpest objection to Jev concerns what that guarantee is actually worth:
"Zero hallucination" = schema guarantee, not correctness guarantee — understand this distinction before building.
That lands squarely on the agent. Its DONE operation is a typed decision like any other, and the README concedes that a DONE choice still requires independent outcome verification. A well-formed DONE that is wrong looks exactly like a well-formed DONE that is right.
Independent benchmarking of Jev has only just started. The jev-capability-atlas project ran Jev and the Laya family on identical inputs for the first time and found the trade-off is real in both directions:
Laya's fine-tuned specialist does beat Jev by 3 points on its own training distribution
— Zaious, jev-capability-atlas
— at five times the calibration error, and below an input-blind baseline once taken off its own distribution, where the same testers found Laya far behind in Chinese. Jev has its own language problem: TypeSafe states that Jev is less accurate in CJK, and the atlas set out to measure it rather than take that on trust. On Chinese proofreading it caught 67% of wrong characters at a confidence threshold of 0.5, with a 12% false-alarm rate on the SIGHAN set. Raising the threshold to 0.7 cut the false alarms to 5% and the catch rate to 38%. And there is a commercial caveat attached to the cost argument that the agent's economics depend on:
vendor says it can't prove the price isn't subsidized — treat it as today's price.
One more objection comes from a sibling project rather than this one: a tester on jaredpalmer/kev found a typed-decision model that handled threshold comparison and ordinal mapping correctly but could not subtract two dates, and fixed it by putting the day count into the state instead of asking for it. Different model, same lesson. Typed decisions are only as good as what you hand them.
Where this fits in a pipeline
The pattern worth stealing is not the model. It is the split: do the deterministic work deterministically, and spend a model call only on the one step that genuinely needs judgement. That is why the protocol-call count dropped by an order of magnitude — most of what an agent loop does was never a reasoning problem.
You can build that shape today in Latenode without any of the pieces above. The cloud headless browser gives you full Puppeteer, so navigation, waits, form fill and extraction are code that does the same thing every run, on browsers you do not have to install, patch or keep alive. How many of those runs go at once is a ceiling you size for rather than a free variable: the quantity is called max execution workers, the number of workflow runs a workspace can process simultaneously. A paid plan includes five, and beyond that concurrency is a reserved-worker add-on at $10 per worker a month. Batch a thousand pages and they queue behind that number. Around it, a JavaScript node with the NPM registry handles state and validation, and you call a model — from the catalogue on /ai-models — only at the branch where the page is genuinely ambiguous. The billing model rewards the same split. Latenode meters the CPU-seconds a run actually consumes, with no per-execution minimum, so a task that finishes in 7.1 seconds instead of 9.5 does cost less — proportionally, and the gap compounds across a batch. The mechanism is worth stating precisely, because it is easy to get backwards: the meter prices runtime, not calls. A thousand browser round trips cost a thousand billable operations on a per-operation platform; here they cost whatever time they take, so a chatty agent loop is expensive only to the extent that it is slow. There is no Jev integration in Latenode, and this article is not claiming one; the useful import is the architecture.
Who should spend time on this
Read the design document if you build browser automation. The idea that the action space should be enumerated by the harness and merely indexed by the model is worth an hour whether or not you ever call TypeSafe.
Do not put it in production this quarter. Its unsupported list is disqualifying for most real sites:
Shadow roots, frames, canvas, uploads, pop-up tabs, nested scrolling, and arbitrary keyboard widgets remain outside this MVP.
— browser-use/jev-ultrafast README
Anything behind an iframe — payment forms, embedded pickers, most consent flows — is out. So is any upload. Add a single-vendor dependency on an early-access API whose pricing its own vendor will not call final, no tagged releases, and a success record of three tasks, and the risk is obvious.
The people who should run it now are the ones who can measure it: a task suite of your own, on your own pages, reported publicly. That is the thing the ecosystem is missing, and it is cheap to produce.
This is how things stood on September 22, 2026. Projects move fast — check the source before you rely on it.
Questions people ask
- Do I need a TypeSafe account to run jev-ultrafast?
Yes. The agent needs TYPESAFE_API_KEY for the decision model and a separate TEXT_MODEL_API_KEY for the small writer model. The example configuration points the second key at OpenRouter and the inception/mercury-2.5 model, with reasoning disabled, but Gemini, GLM or DeepSeek work through the same OpenAI-compatible helper.
- Does the agent look at screenshots of the page?
Not in the default loop. It reads structured state - HTML and ARIA roles, names, values and visible text - and builds an indexed table of candidate elements. Screenshots appear in the local inspector for humans, not in the decision path.
- How long can a single run go on for?
Sixty browser actions and 120 decision requests, whichever comes first. Up to 250 action candidates are kept per observation, and anything truncated past that cannot be selected at all - which is a real failure mode on very long pages.
- How do I pin a version of something with no releases?
You pin a commit hash, which means you own the upgrade decision entirely. There are no release notes to read, no semantic-version signal that a change is breaking, and no tag to roll back to - so budget for reading the diff yourself every time you move, and vendor the dependency if a silent upstream change would hurt.
- What does a decision cost?
TypeSafe lists input at $0.042 per million tokens with output free. The measured Google Flights run also spent about $0.00006 on two calls to the small text model, so at this scale the browser time costs more than the inference.