
Laya on the Neural Engine: 4.98 ms and 0.154 J per decision
Published September 22, 2026
A decision priced in milliseconds and joules
mizorewww/laya-coreml takes Laya's typed-decision checkpoints, converts them to Core ML, and runs them on the Apple Neural Engine. The output of that work is not a new capability. It is a price list.
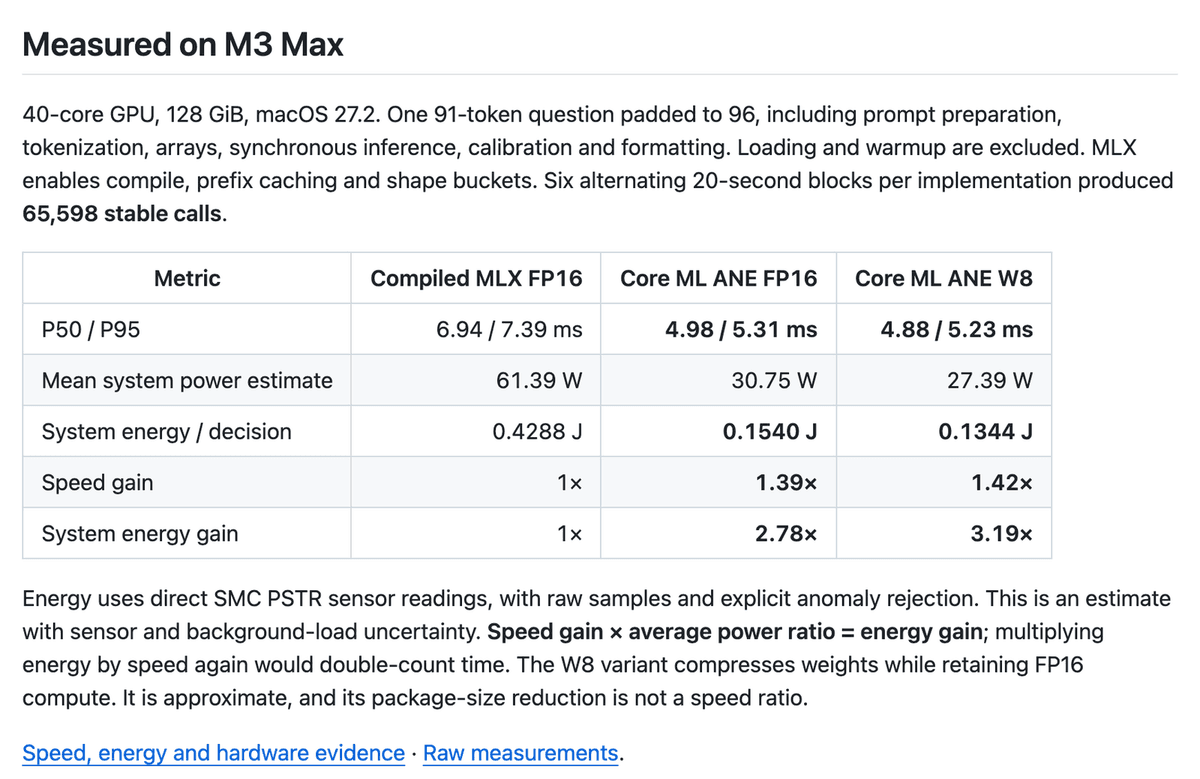
One short multilingual decision: 4.98 ms P50 / 5.31 ms P95 on M3 Max with ANE FP16.
The same table puts compiled MLX FP16 at 6.94 / 7.39 ms, and energy per decision at 0.1540 J for the ANE against 0.4288 J for MLX — a 2.78× improvement over 65,598 stable calls, with energy read from the SMC PSTR sensor rather than modelled. Ten thousand decisions on the Neural Engine is about 1.5 kJ, or 0.43 Wh. That is a number you can budget against, and it is the reason this port exists rather than another wrapper.
Read the test conditions before you spend it, though.
One 91-token question padded to 96, including prompt preparation, tokenization, arrays, synchronous inference, calibration and formatting.
The question is 91 tokens; padding takes the tensor to 96; and 96 is the whole budget. The ANE bundle's total limit is 96 tokens, counting the question, the options and any carried state, and a longer request raises a capacity error. So the headline is measured with the box full — the right way to measure it, and also a warning that there is no headroom to find later.
What is in the box matters more than the milliseconds, and this is the part to check before you port anything.
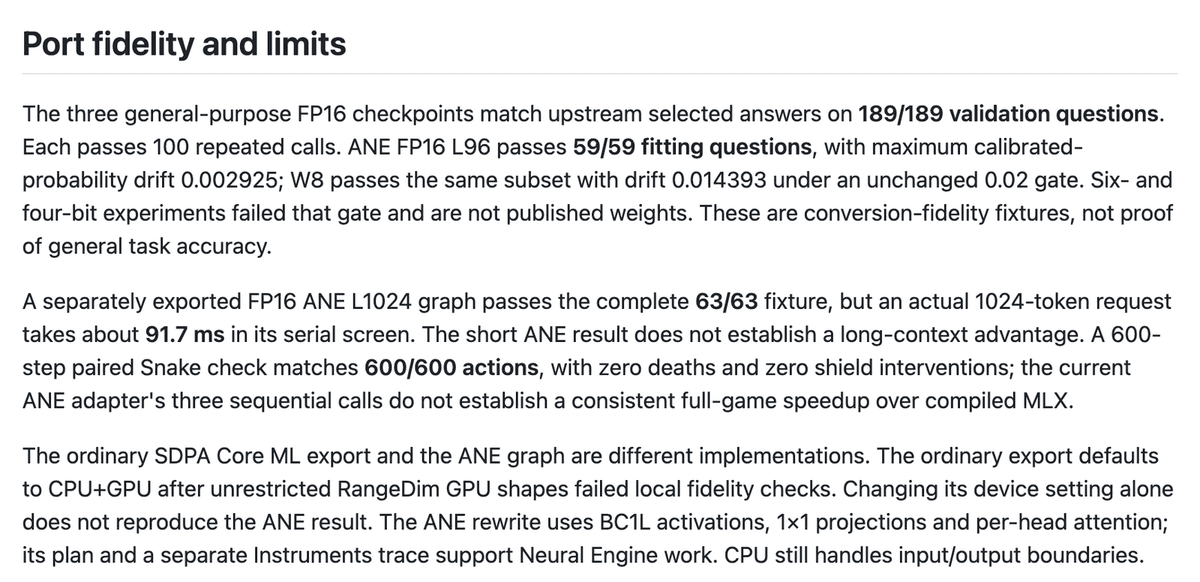
The three general-purpose FP16 checkpoints match upstream selected answers on 189/189 validation questions. Each passes 100 repeated calls.
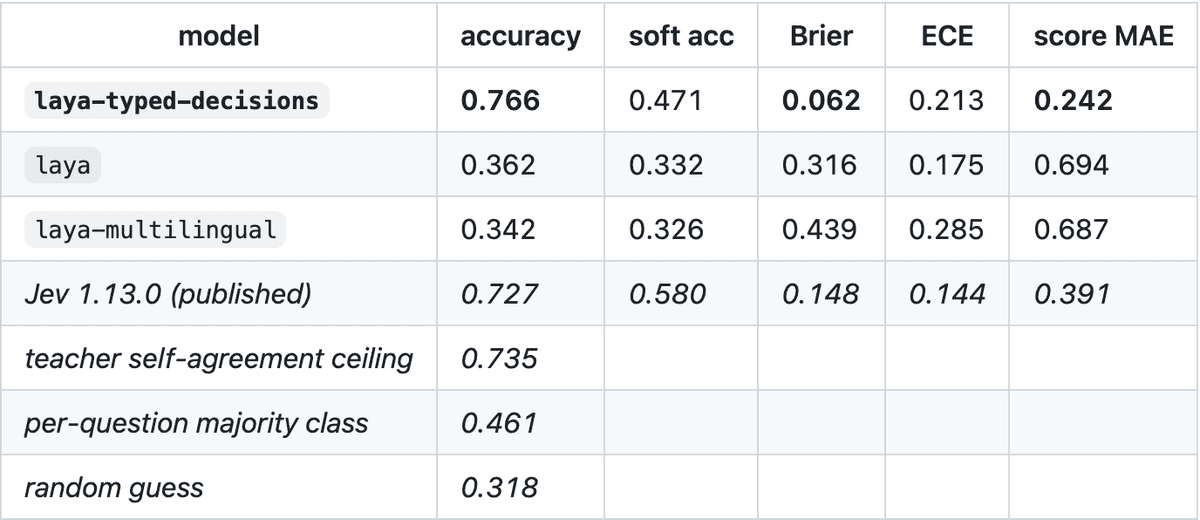
General-purpose is the operative phrase. On upstream's typed-decisions benchmark the general-purpose checkpoints score 0.362 and 0.342, below the 0.461 a per-question majority-class guess achieves; the 0.766 that makes Laya look strong belongs to a task-specific fine-tune. What no page on either side reports is an accuracy figure for the bundle that produced the 4.98 ms. Latency is measured per bundle; accuracy is measured per upstream checkpoint; nobody joins the two columns.
The loop is the thing that has to be cheap
Eight repositories carry the Laya name in this week's feed, and the two with measurements attached are runtime ports by the same author: an MLX runtime, then this Core ML one. Neither adds a capability to the model. Both exist to make one decision cheap enough to sit inside a loop that will run it thousands of times — the port's own end-to-end check is a 600-step Snake game, matched action for action against the MLX build.
That is the premise the cluster is acting on: that a network round trip does not fit inside a frame. Worth naming as a premise, because nobody here has published a timing of the hosted alternative next to their own. What laya-coreml did publish is the other half of the budget, which almost nobody measures.
A separately validated W8 palette variant reached 4.88 ms and 3.19× energy improvement.
The same paragraph adds that these are single-question results rather than full Snake frame times, and that the tenfold improvement the work set out to find was not achieved. Two developers who tried the same move on other runtimes then published measurements on a different axis entirely: not how fast the converted model answers, but whether the answer and the confidence attached to it survive the conversion.
Parity fixtures prove the answer did not change, not that it was right
The port's validation is thorough and unusually clear about its own scope. The ANE FP16 build passes 59 of 59 fitting questions with maximum calibrated-probability drift of 0.002925; W8 passes the same subset at 0.014393 against an unchanged 0.02 gate; six- and four-bit experiments failed that gate and were never published as weights. And then, in the same paragraph:
These are conversion-fidelity fixtures, not proof of general task accuracy.
That distinction is exactly where the critics land. On Hugging Face, the author of a quantised web port reports what happens when you reach for the obvious compression:
Ordinary dynamic INT8 destroys this model. onnxruntime.quantization.quantize_dynamic drops argmax agreement to 69% with a worst-case probability shift of 0.99.
— nvkudva, laya-web-q8 model card
Quantising the MatMuls alone is catastrophic while quantising embeddings alone survives, which points at activation outliers rather than weight precision. A developer working the same problem in a browser port put the trade in one line:
The difference is the quantization scheme, not the checkpoint, and it is also where the twentyfold speed difference comes from.
— a-voronkov, laya-web-poc PR #16
Calibration is the second hole, and it is a sequencing problem rather than a quantisation bug:
The shipped temperatures were fitted by the original author, not refitted after quantization.
— nvkudva, laya-web-q8 model card
Upstream agrees on the magnitude, in its own README:
Refitting one temperature per (question type, option count) on held-out data moves mean ECE 0.466 -> 0.081 (laya) and 0.314 -> 0.106 (laya-multilingual).
The Core ML port has already caught one instance of this going wrong: a shipped temperature of 0.1006 for the eleven-plus-options bucket, sharp enough to report a coin flip as near-certainty, now clamped with a warning named at load. A fixture that compares two models' probabilities cannot see an error both of them inherit.
The third objection never touches the silicon at all. It lands on the router that picks which checkpoint the silicon runs.
128/200 German utterances (64%) went to the English checkpoint.
An undecided language guess is treated as English, and passing lang="de" recovers full accuracy, so the model is fine and the routing is not. That is a 20-point swing on short Latin-script text, decided by a heuristic that reports full confidence while getting it wrong.
What nobody has produced is the comparison most readers want:
Accuracy and calibration claims for laya-mlx haven't been independently verified against a shared benchmark like JevBench; the published numbers cover latency, throughput, and memory only.
Notice what that leaves out. Every measurement above is local against local — Neural Engine against compiled MLX on the same laptop, one question at a time. Nobody has published a hosted round trip measured beside it, so "faster than the API" is still the premise these projects start from rather than a result any of them reports.
Fitting it into something that ships
The 5 ms number holds for short, fixed-shape decisions and stops holding the moment you leave the box:
A separately exported FP16 ANE L1024 graph passes the complete 63/63 fixture, but an actual 1024-token request takes about 91.7 ms in its serial screen.
Eighteen times the latency. The project draws the conclusion itself:
The short ANE result does not establish a long-context advantage.
So the deployable version is a small fixed prompt, a short option list, explicit language selection instead of auto-routing, and temperatures you fitted yourself on your own labelled data after conversion. Budget the labelling. That is the real integration cost, not the export.
The shape underneath all of this is a gate: a typed decision is a classifier, and a classifier earns its keep in front of slower work, so most inputs never reach the model call, the scrape or the person. On a laptop the gate is the Core ML bundle and the saving is that the expensive thing is never asked. In a hosted pipeline the gate is instead the first step inside the run, and that is a shape Latenode's meter suits: it counts the CPU-seconds a run actually consumes — runtime, not the number of nodes or API calls — and there is no per-execution minimum charge, so a run that ends at the gate is billed for the seconds it spent rather than as a whole execution. The step doing the gating is an ordinary node: one of the roughly 335 models in the catalogue, or a JavaScript node, which can install any NPM library. The free tier includes 10,000 CPU seconds a month and five active workflows. None of that runs the ANE bundle, which stays on the laptop; what moves between the two is the shape, not the artefact.
Who should port this week
Port it if you have a fixed, low-cardinality decision inside a loop on Apple silicon, your prompt and options fit in 96 tokens, you can state the language rather than letting the router guess it, and you have labelled examples to refit calibration with. Check which upstream checkpoint your bundle carries before you promise anyone an accuracy number — the port is explicit that what it converted is the general-purpose family, and the general-purpose family is not the row that beats the teacher. For that reader the speed and energy numbers are real and reproducible, which is more than most on-device claims manage: 4.98 ms, 0.154 J, sensor-measured, 65,598 calls behind them.
Skip it if you were hoping to swap a hosted decision endpoint for this and keep everything else. The published work does not support that swap — no shared-benchmark comparison exists, the shipped probabilities are miscalibrated until you fix them, and auto-routing silently costs 20 points on short Latin-script non-English text. There is also a ceiling on how many labels you can ask for:
I've found they start to fail the more classifications you have, long before your typical ML classifier.
If you are evaluating this as an architecture rather than a package, the honest reading is narrower than the star counts suggest: the evidence supports putting one small, well-specified decision on the Neural Engine at a known cost per call, and it does not yet support putting your judgment there.
This is how things stood on September 22, 2026. Projects move fast — check the source before you rely on it.
Questions people ask
- Is laya-coreml an official Apple or Convai release?
No. The README describes it as an independent port under Apache-2.0 and states plainly that it is not an official Convai Innovations or Apple release. Treat the weights and the benchmark harness as community work with a NOTICE file, not as a vendor SDK with a support channel.
- Does the W8 variant make the model meaningfully faster?
Barely. It reports 4.88 ms P50 against 4.98 ms for FP16 - 1.42× against 1.39× over compiled MLX. The gain is in power, 27.39 W against 30.75 W mean system draw, and in package size. The README warns that the package-size reduction is not a speed ratio, because W8 compresses weights while compute stays FP16.
- Is the long-context export also running on the Neural Engine?
Not by default. The ordinary SDPA Core ML export and the ANE graph are different implementations, and the ordinary one defaults to CPU+GPU after unrestricted RangeDim GPU shapes failed the project's local fidelity checks. Flipping its device setting does not reproduce the ANE result - the ANE path is a rewrite using BC1L activations, 1x1 projections and per-head attention.
- What do I actually need in order to refit calibration?
Labelled examples from your own traffic, bucketed by question type and option count, with one temperature fitted per bucket after conversion rather than before. Nothing in the port does this for you. Two things help while you work: the unclamped values stay reachable as agent.temperature_raw and agent.temperature_by_options_raw, and a RuntimeWarning at load names every bucket the port had to clamp.
- Does 0.154 J mean the chip spends 0.154 joules?
No. It is a whole-system estimate from direct SMC PSTR sensor readings, so it includes whatever else the laptop was doing, and the README flags sensor and background-load uncertainty. Loading and warmup are excluded from the per-decision figure, which matters if your process is short-lived.
- Can I compress below 8-bit to fit a smaller device?
Not with published weights. The port's six- and four-bit experiments failed its 0.02 calibrated-probability drift gate and were never released; W8, at 0.014393 drift, is the floor it was willing to ship. Note that W8 compresses weights while compute stays FP16, so it is not the same operation as quantising activations, which is where the other runtimes came unstuck.