
Nimble: 2,676 examples to get within three points of Jev
Published September 22, 2026
A recipe, not another endpoint
Bespoke Labs published nimble on 18 September: a LoRA adapter that turns Qwen3.5-9B into a typed decision model — pick one of these candidates, apply this policy, score this against this rubric — and, more usefully, the entire pipeline that produced it. Curation code, training configuration, evaluation harness, all Apache 2.0. The adapter itself is about 165 MiB and needs the 18 GB base model sitting beside it.
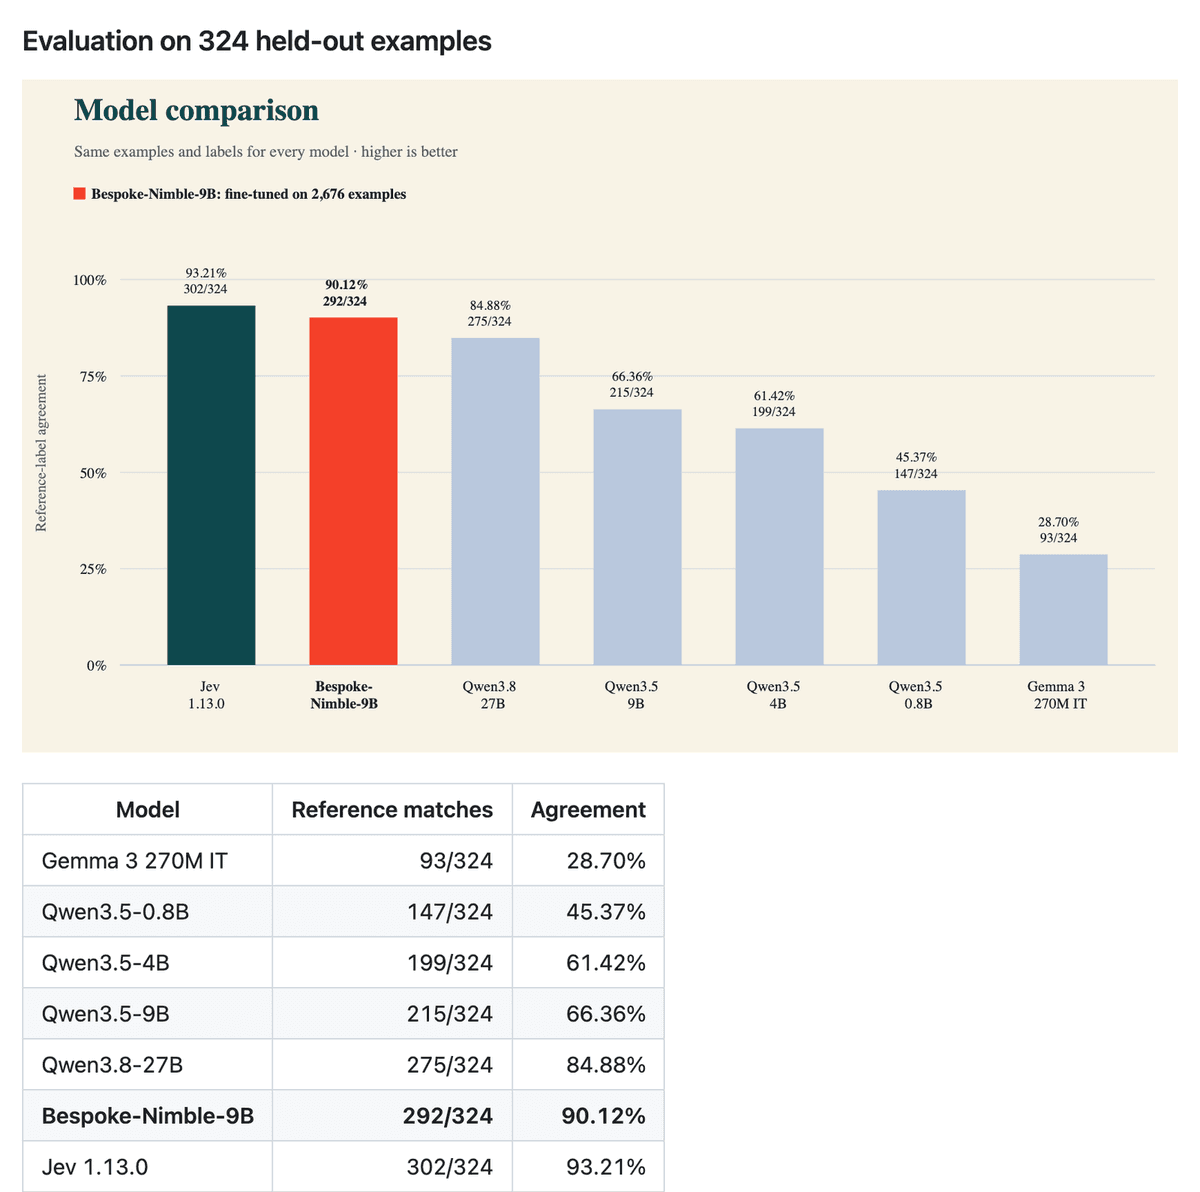
What that changes for a reader is the arithmetic on a question people have been arguing without numbers: what it costs to stop calling someone else's decision model. On the project's frozen held-out set of 324 examples, the fine-tune agrees with the reference label 90.12% of the time. TypeSafe's Jev 1.13.0 gets 93.21% on the same examples. The untuned base model gets 66.36%. So the LoRA closes most of a 26.85-point gap and leaves three points on the table.
Note that we did not distill from Jev.
That sentence is doing real work. It means the recipe is a recipe and not a copy, and it means the three points are the cost of building the training data yourself rather than the cost of a lossy imitation.
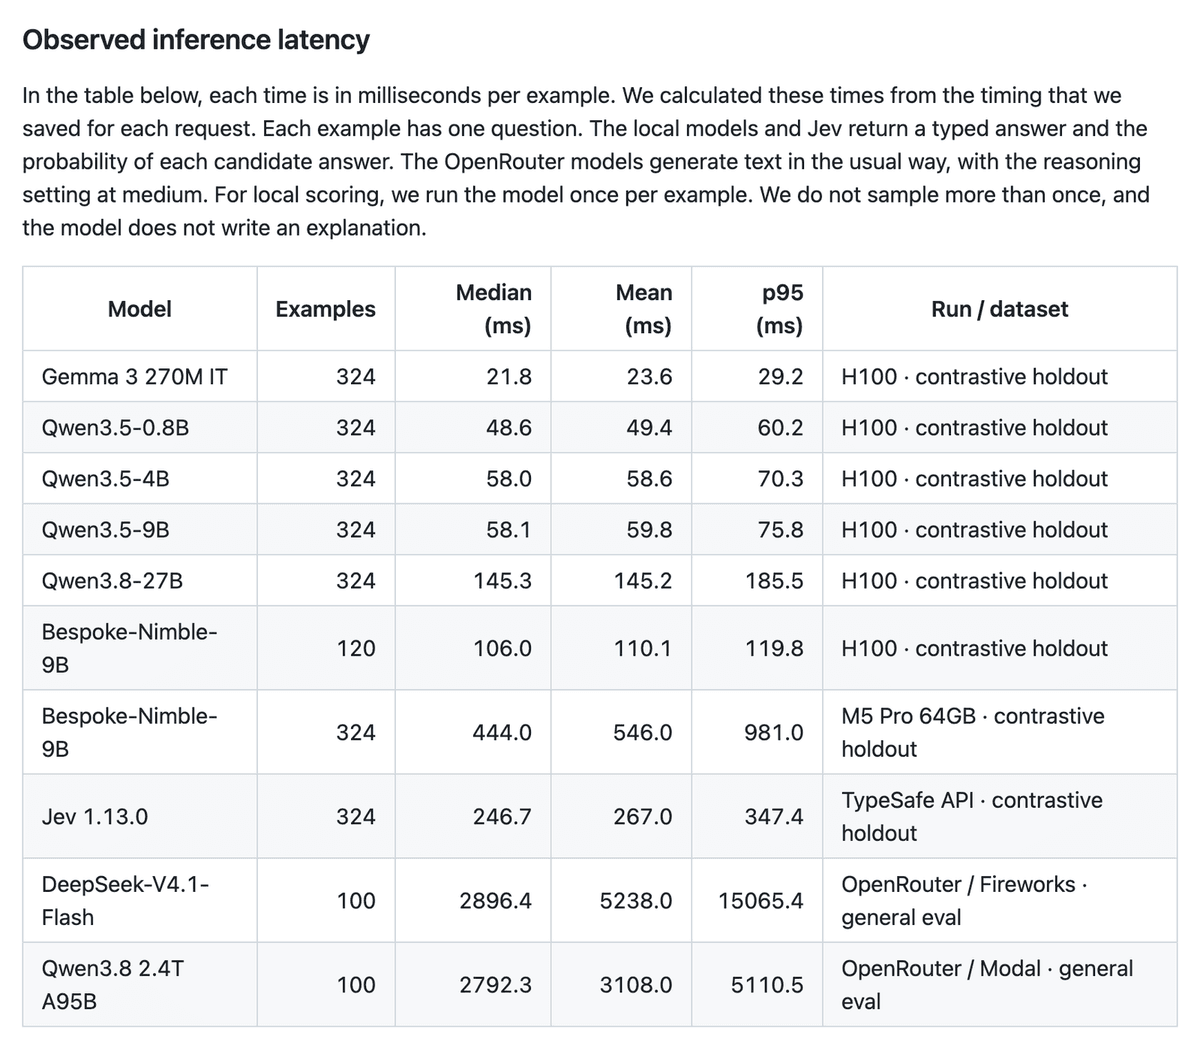
Locally it is also faster than the call it replaces, with the caveat printed in the same table. Median 106.0 ms per example on an H100 against 246.7 ms through the TypeSafe API. On an M5 Pro 64GB the same adapter takes 444.0 ms median, 546.0 mean, 981.0 at p95 — which is the end of the laptop version of the pitch. Higher up the same table, the untuned Qwen3.5-9B base runs 58.1 ms over all 324 examples, and the repository does not explain what the adapter adds. The fast figure also does not rest on the same sample as everything it is compared against.
Their recorded times are also not from a controlled serving test.
The part of the wave that showed its working
Jev shipped closed, and September filled up with lookalikes — an AINews roundup this week catalogued six of them and guessed at the architectures, because guessing was all anyone could do. Nearly all of them published a speed number and an endpoint.
a lot of demos emphasized speed more than quality, and there is still no standard benchmark for this category.
Nimble is the entry that handed over the expensive step instead: how the training data was made. Bespoke call the method contrastive data curation. You write two examples that are nearly identical.
They differ in one relevant fact, and this difference changes the correct answer.
The documented example is a refund policy where only Mira may authorise refunds on an account; the paired version swaps the name on the signed authorisation to Noah, and the correct answer flips from true to false. Everything else — the question, the policy, the phrasing — holds still. The pipeline enforces that with a mechanical locality check: each proposed pair may change one sentence and at most eight whitespace-separated words, measured by a token diff. Separate model calls then verify the facts in each example, and a deletion test confirms that removing either evidence sentence leaves the focus fact genuinely unknown.
That produced 2,676 examples across ten subject categories, generated with GPT-5.6 Terra and checked with GPT-5.6 Sol, then a single epoch of LoRA training — 335 optimizer updates at effective batch size 8. Tuning ran on L40S; the final fit ran on an H100. The whole thing came together at the speed the week was moving at.
We built Nimble in one day, so expect some rough edges.
Where it loses is more useful than by how much
The README sends you to an external comparison: thirteen public, human-labeled subsets, outside the training categories, both models scored on the same records.
That is a gap of 1.2 macro points in Jev's favour across tasks that are all outside Nimble's training categories.
— Nimble public benchmarks guide
74.8% macro against 76.0%. That gap is the figure that will get quoted, and it is the least informative line on the page.
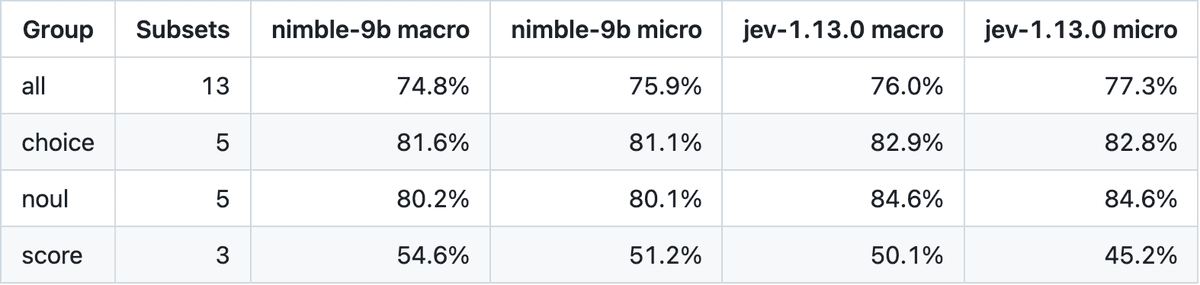
Split by group, the fine-tune loses choice 81.6 to 82.9 and loses noul 80.2 to 84.6, and wins score 54.6 to 50.1, with the micro figures further apart at 51.2 against 45.2. Read as three results, that says a model trained on 2,676 self-made examples beats the vendor on rubric rating and trails it on classification. The per-subset accuracy table printed above those averages says something narrower and more useful, because it carries a McNemar p-value on every row. The score win is one dataset deep: summeval-relevance at 49.2 against 35.0, p=0.0004, while helpsteer2 is 4.9 points apart at p=0.3232, which is not significant, and the fine-tune loses the third score subset, summeval-consistency, 75.7 to 81.2. The choice group's 1.3-point deficit, meanwhile, averages two significant losses — massive-de-DE at p=0.0169, vitaminc-dev at p=0.0125 — against one win that is not significant. So the honest version of the split is not "wins rubric rating": it is that one summarisation dataset carries the only unambiguous win, and the losses that survive a significance test are spread across the classification subsets.
The README's split of the same training set by task type suggests a cause rather than a coincidence. Score is the largest block at 932 examples, against 888 for Noul and 856 for Choice. The model is strongest, relative to the vendor, on the task type it saw most of.
One row deserves to be lifted out of the averages entirely. paws is the eighth of the thirteen subsets: adversarial word scrambling, where two sentences share most of their words and mean different things. Type noul, 250 records. The fine-tune scores 82.8%, Jev 89.2%, and the page marks the difference significant at p=0.0025. That 6.4-point gap is wider than any of the group averages, and it lands on a task built exactly like the training data: minimally different sentence pairs that mean different things. PAWS is contrastive curation's own idea, written as an adversarial test by other people. The method's most distinctive claim is weakest on the task the method exists for.
The authors are blunt about the boundary of all of this.
We trained Bespoke-Nimble-9B on 2,676 examples that we curated. So it's performance will depend on this data and the domains it comes from.
(The typos are theirs, and are the one-day build showing.) The domain reach is narrower than even that sentence suggests, and the README prints the reason as a table: a training count and a held-out count for each of the ten categories.
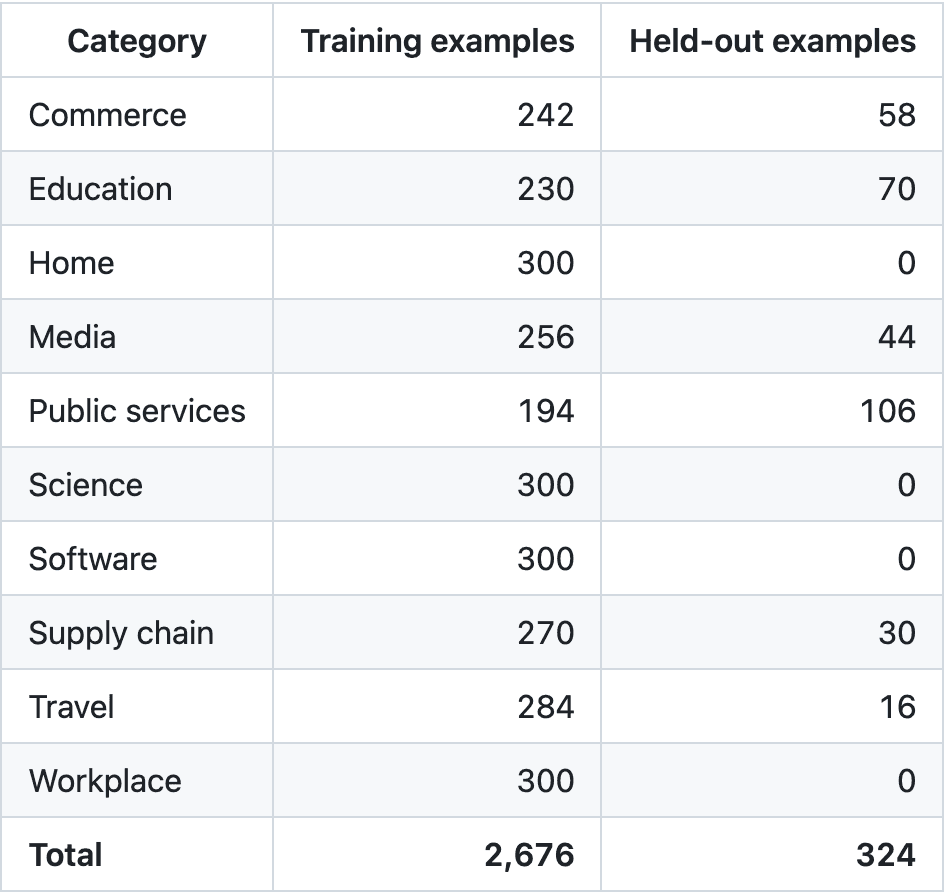
Four of the ten hold-out counts are zero: Home, Science, Software and Workplace, at 300 training examples each. The entire 324-example evaluation comes from the other six — Public services 106, Education 70, Commerce 58, Media 44, Supply chain 30, Travel 16. So the 90.12% is measured over six-tenths of the surface the model was trained on, and the four unmeasured tenths are the four largest training blocks in the set. Not weak: unreported.
Outside the project, the complaint is about where the labels came from at all.
Of course, not enough people are talking about the data side, which is acknowledged to be 100% synthetic.
Acknowledged is the right word, and the acknowledgement is unusually clear-eyed:
All of the labels are synthetic: a model checked them, and no person has reviewed them.
The README adds the reason this bites: separate calls to the same model can make the same mistake, so the check can miss what the generator got wrong. Training data and evaluation data were produced by the same family of generators, which means a shared blind spot would raise the score and lower the accuracy at once, and nothing in the repository would show it.
The held-out set is small in a second way that has nothing to do with categories. Its 324 examples are 162 closely related pairs, and the README counts where they were drawn from:
All of them come from only six source families, so this is a narrow test.
Whether those six families are the same six categories the holdout covers, the README does not say, and the benchmarks guide uses "families" in a different sense elsewhere — a count of source documents behind a subset, such as 31 behind squad2's 299 records. Either way the author's word for it is the right one: narrow.
Two independent critiques sharpen that into something you can test for. An engineer benchmarking Jev in an agent harness found the failure mode that a schema guarantee cannot catch:
High confidence means the model is sure it applied your definition — including your mistakes
— Benchmarking Jev in an agent harness, DEV Community
They report wrong routings arriving at confidence 1.0. Fidelity to your schema is not correctness, and a fine-tune inherits your definitions more literally than a vendor model would. Separately, a Johns Hopkins group measured what a label-only comparison hides: across 588 results, every final label was correct while 581 downstream outputs were exact.
the workflow can return the expected verdict while passing an incorrect quantity to subsequent analysis.
Agreement with a reference label is exactly a label-only score. Both of Nimble's headline numbers are of that kind.
The last objection comes back to paws, from someone with a horse in the race. On the project's issue tracker, a commenter posting as m0at pits their own zero-weight edge discriminators against Nimble-9B and Jev on a reconstructed 324-sample suite of BoolQ, MultiNLI and PAWS, and reports their implementation reaching 100% at sub-millisecond latency. Treat a self-run comparison on a self-rebuilt suite with the scepticism it invites. The mechanical part of the argument survives who is making it:
Base small models struggle significantly on PAWS (Gemma 3 at 41.2%, Qwen 3.5 at 45.4%)
— m0at, bespokelabsai/nimble issue #3
The reason given is that unigram overlap between the two sentences runs above 85%, so a model weighing words rather than their order has almost nothing to grip. That is a claim about the shape of the task rather than about anyone's product, and it points at the same subset where Bespoke's own suite records the fine-tune's significant loss.
Using n-gram order sensitivity (specifically trigram Jaccard divergence) reliably discriminates semantic flips without requiring generative rollouts.
— m0at, bespokelabsai/nimble issue #3
If a trigram statistic with no weights can separate the cases a fine-tuned 9B model gets wrong, the interesting question is not whether to own the model. It is which of your decisions needed a model at all.
Where a model like this earns its place
A typed decision model is a classifier, and classifiers are most useful as a routing step in front of slower work: decide first, then spend. The refund question above is the archetype — settle "is this authorised" in one typed call, and let the branch that reads documents, writes to a ledger or pages a human run only when the answer says so.
Nimble's numbers change the shape of the build-or-buy decision rather than settling it. If your traffic looks like one of the six categories the holdout covers, you have a published figure to argue from. If it looks like Home, Science, Software or Workplace, nobody has published a figure — including the people who trained on those categories — and your first job is a held-out set of your own, labeled by someone who will be blamed if it is wrong. The curation method transfers cleanly. The labels do not transfer at all.
Whichever model ends up making the call, the workflow around it is the same, and it is worth building so that the cheap path stays cheap. On Latenode that is straightforward to price, because the meter counts the CPU-seconds a run actually consumes rather than nodes or API calls, and there is no per-execution minimum — so a run that classifies, takes the short branch and exits costs proportionally less than one that goes the long way round. A JavaScript node can install any NPM library, which keeps the work around a decision — parsing, validation, the branch itself — ordinary code rather than configuration. The free tier is 10,000 CPU-seconds a month across 5 active workflows. How far that goes is a question about your traffic, not about the meter.
Who should clone this, and who should not
Clone it if you have a narrow, stable decision surface and the stomach to label data: the transferable asset here is the curation pipeline, not the weights, and the scale it worked at was 2,676 examples across ten categories and a single epoch of 335 optimizer updates. What that cost in hours, the repository does not say. Clone it if your task looks specifically like rating summary relevance, because that is where the one unambiguous win sits — summeval-relevance, 49.2 against 35.0 at p=0.0004 — and it is a single dataset rather than a category: the other two score subsets are a statistical tie and a loss. Clone it if you want to see what a decision model looks like with the data step visible, because almost nothing else in this wave shows it.
Skip it if you are shopping for a drop-in Jev replacement. It is three points behind on the domains it was built for, 6.4 points behind at p=0.0025 on paws, the adversarial-paraphrase subset built the way its own training data is built, and the authors tell you plainly not to expect generalisation. Skip it if the deployment target is a laptop: 444 ms median and 981 ms at p95 is a different product from 106 ms on an H100, and the H100 figure was measured on 120 examples while everything it is compared to was measured on 324. And skip it if you have no labeled data of your own, because what produced 90.12% was 2,676 curated examples, not a LoRA rank.
The number worth watching is not the three-point gap. It is whether anyone runs this recipe on data a human has actually read, and reports what changes.
This is how things stood on September 22, 2026. Projects move fast — check the source before you rely on it.
Questions people ask
- What licence is Nimble under, and what do I actually download?
Apache 2.0. The release is a LoRA adapter of roughly 165 MiB, plus the tokenizer, the prompt builder and reference inference code. It is not a standalone model: you supply Qwen3.5-9B yourself, which is another 18 GB or more, and either merge the adapter or load it alongside the base.
- What hardware and settings does the published run use?
An NVIDIA GPU with BF16 support; the repository reports testing on PyTorch 2.8.0 with CUDA 12.8. Bespoke tuned on L40S and ran the final fit and evaluation on an H100. The published configuration is LoRA at rank 16, learning rate 5e-5, batch size 2 with gradient accumulation 4, a 2,048-token prompt limit and random seed 17; the training guide sets max steps at 1,005 with 101 warmup steps.
- Can I run inference on Apple Silicon?
Yes. The repository lists Apple Silicon through MLX alongside the CUDA path, and the published evaluation includes a full 324-example run on an M5 Pro 64GB. The practical constraint is memory for the base model, not the adapter, which is small enough to be an afterthought.
- Can I point the curation pipeline at a different generator model?
Yes. The defaults live in the curation profiles module, and they are set per stage rather than globally: training contrasts and evaluation generation default to different models, at low and medium reasoning respectively. Changing either means editing that module, and nothing in the repository reports what happens to the published numbers when you do, so a swap makes the results yours to re-measure.
- Would a bigger untuned model do the same job?
Not on this test. On the same 324 examples the untuned Qwen3.8-27B — three times the parameters — reaches 84.88%, which is 5.25 points below the 9B fine-tune, and the ladder falls away quickly beneath it: Qwen3.5-4B at 61.42%, Qwen3.5-0.8B at 45.37%, Gemma 3 270M IT at 28.70%. On the domains it was trained for, 2,676 curated examples buy more than three times the weights do — which is the case for the recipe, and it is only a case about those domains.
- Does the model explain its answers?
No, and that is deliberate. Local scoring runs the model once per example, with no repeated sampling and no written rationale. What comes back is a typed answer plus a probability for each candidate, which is what makes it cheap enough to sit in a hot path, and also what leaves you with nothing to read when it is wrong.