

Quick answer: what a data pipeline is
Drawing on the two definitions below, a data pipeline is a set of automated steps that moves data from one or more sources to a warehouse, a data lake or an app, usually transforming it on the way. AWS calls it a series of processing steps that prepares enterprise data for analysis. IBM describes a system that ingests raw data from multiple sources, transforms it and loads it into a data store for analysis and operational use.
The definitions in this guide come from documentation by AWS, Google Cloud, Microsoft, IBM and open-source projects such as Apache Airflow, Apache Kafka and dbt, as it stood in October 2026.
The parts of a data pipeline
According to IBM, which counts three core stages, the architecture comes down to data ingestion, data transformation and data storage. The AWS page groups the components differently, as sources, transformations, dependencies and destinations. In practice, a working pipeline has these parts:
"Transformations are operations, such as sorting, reformatting, deduplication, verification, and validation, that change data. Your pipeline can filter, summarize, or process data to meet your analysis requirements."
Source: aws.amazon.com
- Sources: where the data starts. According to AWS, a source can be an application, a device, a database or a stream.
- Ingestion: how data gets in. AWS says sources can push data into the pipeline, or the pipeline can pull it with an API call, a webhook or a data duplication process.
- Processing or transformation: the work that changes the data. AWS names sorting, reformatting, deduplication, verification and validation, and says a pipeline can also filter or summarize data to meet analysis requirements.
- Storage or destination: where the result lands. IBM names data stores such as a data lake or a data warehouse. In a small setup, the destination can just as well be a spreadsheet or a business app.
- Orchestration and scheduling: what runs each step in order. In Apache Airflow, a workflow is defined as a Dag, which encapsulates everything needed to run it: its schedule, its tasks, which are discrete units of work, and the task dependencies that set the order and conditions of execution.
- Monitoring: how you know a run worked. Microsoft's Azure Data Factory documentation says that once a pipeline is deployed, you monitor scheduled activities and pipelines for success and failure rates.
Security runs through all of these parts. IBM says access controls are necessary for protecting sensitive data in motion, with authentication, authorization and encryption limiting access to approved users and systems. AWS also advises regular audits of pipelines that handle sensitive data.
How a data pipeline works: one example from start to finish
Take a small online store that wants one dashboard with yesterday's revenue next to yesterday's ad spend. Today someone pastes two exports into a spreadsheet every morning. A pipeline does the same job like this:
- Extract the orders. The pipeline pulls new orders with an API call or receives each new one through a webhook. If orders live in your own database, change data capture can record each change to its tables and rows, so only changed orders move.
- Extract the ad spend. A second task asks each ad platform's reporting API for the previous day's spend per campaign.
- Load the raw data. Both feeds land unchanged in warehouse tables, so the original records stay available for rebuilds.
- Transform inside the warehouse. SQL models drop duplicate orders, reformat dates and currencies, join spend to orders by campaign and day, and summarize everything into one daily table. Loading first and transforming later is the extract, load, transform (ELT) pattern.
- Schedule the run. An orchestrator starts both extracts each morning and runs the transformation only after both loads succeed. That is what task dependencies are for.
- Check quality. Tests confirm that order IDs are unique, amounts are filled in and spend is never negative. If a test fails, the run stops before wrong numbers reach the dashboard.
- Serve the result. The dashboard reads only the finished daily table, so marketing and finance look at the same revenue figure.
- Watch and recover. Run history shows which step failed, and you rerun that step instead of the whole job.
The tests in step 6 catch bad data after it arrives. When a source belongs to another team or a vendor, also write down what the pipeline relies on as a versioned data contract: the fields, their types and the meaning of key values such as revenue. Check each load against it, so a change upstream stops the run with a clear reason instead of reaching the dashboard.
For the store, this means no manual exports and one agreed definition of revenue. The numbers arrive at the same time every day, and the raw history is there to reprocess when a source sends bad data.
Types of data pipelines
IBM says batch processing loads batches of data into a repository at set time intervals. IBM adds that it is usually the best fit when there is no immediate need to analyze a dataset, for example monthly accounting. Streaming data pipelines, also called event-driven architectures, work differently. IBM describes them as continuously processing events from sources such as sensors or in-app user interactions, with lower latency than batch systems.
| Type | How data moves | Typical latency | Example |
|---|---|---|---|
| Batch | Batches at set intervals | Set by the run schedule | Monthly accounting |
| Streaming (event-driven) | Continuous flow of events | Lower than batch | Sensor or in-app events |
| ETL (extract, transform, load) | Transform before loading | Depends on schedule or trigger | Cleaned data into a warehouse |
| ELT (extract, load, transform) | Load raw, transform in target | Depends on schedule or trigger | Raw data modeled in warehouse |
| Change data capture (CDC) | Row changes sent as events | Set by consuming pipeline | Database changes to warehouse |
The rows overlap. Batch and streaming describe timing, while ETL and extract, load, transform (ELT) describe where the transformation happens. So a nightly batch job can also be an ETL job. IBM says streaming pipelines are commonly used with change data capture (CDC) tools, which capture changes made to source databases and publish them as events for downstream systems to process. Microsoft defines CDC as recording activity on a database when tables and rows are modified. As a typical consumer, it names an ETL application that incrementally loads change data into a data warehouse.
A big data pipeline is not a separate type either. It is the same batch or streaming pattern at higher volume. Google Cloud, for example, describes Dataflow as unified stream and batch data processing at scale. Vendor latency figures, such as the two in the cloud section below, each describe one product, not a pipeline type.
Pick the freshness the business needs, not the lowest latency on offer, because more frequent runs use more compute. Ask how fresh each report must be: a dashboard read once each morning can come from a nightly batch, and starting its refresh when the load finishes, instead of on a separate timer, avoids runs that find nothing new. One user on r/snowflake gave this advice to an engineer facing high costs: "ask them how real time does it need to be. You have found that higher frequency is more costly."
Structured, semi-structured and unstructured data
IBM says data arrives from SaaS applications, Internet of Things (IoT) devices and mobile devices in structured, semi-structured and unstructured form. According to AWS, structured data maps to a predefined schema and may only need normalization and aggregation. Semi-structured data includes XML or JSON files. Unstructured data, from text documents to images, needs parsing, metadata extraction and enrichment before analysis.
Data pipeline vs ETL and ELT
A data pipeline is not the same thing as ETL. AWS calls an extract, transform, load (ETL) pipeline a special type of data pipeline. It also notes that not all pipelines follow the ETL sequence: some extract data and load it elsewhere without any transformation. IBM states the rule plainly: all ETL pipelines are data pipelines, but not all data pipelines are ETL pipelines.
"An ETL pipeline is a specific type of data pipeline that follows a predefined process for moving and preparing data. While all ETL pipelines are data pipelines, not all data pipelines are ETL pipelines."
Source: ibm.com
Extract, load, transform (ELT) changes one thing. Microsoft's Azure Architecture Center says it differs from ETL solely in where the transformation takes place: in an extract, load, transform pipeline, the transformation happens in the target data store. ETL reshapes data before it reaches the warehouse: AWS says ETL tools copy raw data into a temporary staging area, transform it there and then load it. The load-first approach reshapes it inside.
The load-first order spread because of the cloud. IBM says extract, load, transform pipelines became more popular with cloud-native tools, and that any transformations are applied after the data has been loaded into the cloud data warehouse. Microsoft adds a condition: it only works well when the target system is powerful enough to transform the data efficiently. Microsoft recommends it when the target is a modern data warehouse or lakehouse with elastic compute scaling. If the destination is a small database or a spreadsheet, transform before loading.
Data pipeline architecture on the main clouds
Each major cloud offers managed services for the same layers: getting data in, processing it and running the steps on time.
On AWS, the Kinesis docs say Amazon Kinesis Data Streams collects and processes large streams of data records in real time. For Kinesis Data Streams specifically, AWS says a record can typically be read less than 1 second after it is put into the stream. That is a Kinesis figure, not a typical latency for streaming pipelines in general. AWS describes Glue as a serverless data integration service that supports ETL, ELT (extract, load, transform) and streaming workloads in one service. Glue jobs can run on a schedule, on demand or by an event.
On Google Cloud, Google describes Pub/Sub as an asynchronous, scalable messaging service that decouples services producing messages from services processing them. For Pub/Sub specifically, Google says message latencies are typically on the order of 100 milliseconds. That is messaging latency, not an end-to-end pipeline latency or a figure for streaming pipelines in general. In Google's reference flow, Dataflow reads from Pub/Sub and writes to BigQuery as the warehouse, and Looker provides real-time BI insights. Google says orchestration there is often done with Managed Airflow, which supports Pub/Sub triggers.
On Azure, Microsoft describes Azure Data Factory as a managed cloud service built for hybrid ETL, ELT (extract, load, transform) and data integration projects. In it, you create and schedule data-driven workflows called pipelines. Microsoft calls Data Factory in Microsoft Fabric the next generation of Azure Data Factory and tells newcomers to data integration to start there.
On the open-source side, the Airflow docs describe Apache Airflow as a platform for developing, scheduling and monitoring workflows such as time-based or event-triggered batch data pipelines. The Apache Kafka documentation calls Kafka an event streaming platform.
Data pipeline tools by job
Larger pipelines often use separate tools, one per job.
- Managed connectors: as of September 2026, Fivetran's pricing page lists 700+ fully managed connectors on its Standard plan. Airbyte offers a self-hosted open-source edition called Airbyte Core alongside its managed cloud plans.
- Transformation: dbt's documentation says dbt transforms raw warehouse data into data products from SQL select statements. It works alongside ingestion and visualization tools, so data is transformed directly in the cloud data platform. That makes dbt the transform step in an extract, load, transform (ELT) pipeline. dbt OSS is an open-source distribution of dbt's Rust-based engine under the Apache 2.0 license.
- Orchestration: Apache Airflow workflows are defined entirely in Python. The Airflow docs say teams who prefer clicking over coding may find it a poor fit, because some coding is always required.
- Streaming: Apache Kafka is built for event streaming, which its documentation defines as capturing data in real time from databases, sensors, mobile devices, cloud services and applications as streams of events.
For prices and plan limits, see the data pipeline tools guide on this blog.
Building a simple pipeline without a data team
An automation platform is often enough when the job is small and clear: form entries copied into a spreadsheet, or CRM records sent to a warehouse at low volume. It stops being enough when you need large event streams, heavy transformations across many sources, reprocessing of long history or quality tests on every load. Then use the dedicated tools above.
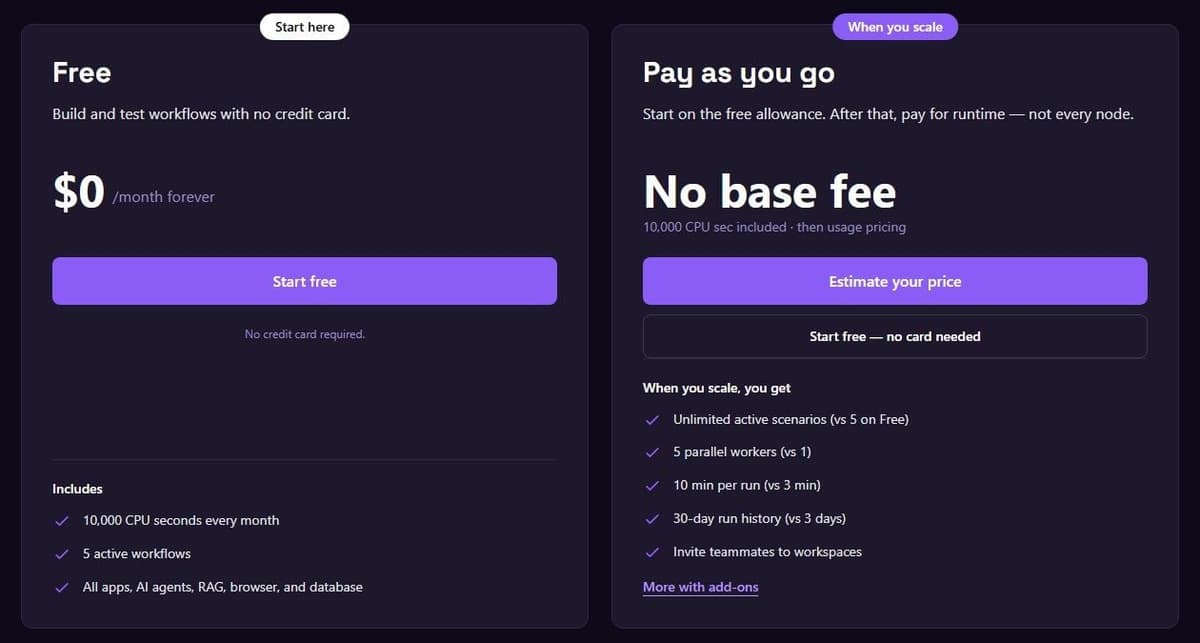
Latenode, which publishes this blog, is one such platform. Its pricing page lists a visual drag-and-drop builder, webhook triggers that are instant on every plan and a built-in database with global variables, and Latenode also offers JavaScript code nodes for custom logic. As of September 2026, Latenode bills workflow runtime in CPU seconds (runs multiplied by average seconds) rather than per operation or step. The first 10,000 CPU seconds every month are free on both plans, Free and Pay as you go. Cost depends on run duration, so CPU seconds are not directly comparable to other tools' tasks, operations or rows. The Free plan allows 5 active workflows and 3 minutes per run. Pay as you go has no base fee, allows 10 minutes per run (60 with a paid add-on) and charges $0.00012 per CPU second from 10,001 to 100,000, less in higher brackets. Nodes that call paid external providers cost extra, in PnP tokens at $1 per token.
If your pipeline today is a set of spreadsheets, there is a simpler first step. A post on r/analytics described one such setup: "Volumes are high, data sources are all excel based, lots of rules to apply each month to achieve the monthly end result." Load each file unchanged into a staging table in a small database, with its file name and load date, then rewrite the monthly rules as SQL views and point the report at those views. That is the extract, load, transform pattern at a small scale, and a file sent twice can be found and replaced instead of counted twice.
Common data pipeline problems
- Bad records slipping through. AWS says reliable pipelines validate records at every processing stage to isolate failures. In dbt, teams can write data quality tests on their underlying data.
- Schema changes. The data formats a pipeline receives change over time, so AWS advises flexible transformation logic that lets the pipeline adapt without complete rearchitecting. Microsoft calls changes to source fields, columns and types schema drift, and says typical ETL patterns fail when that happens because they tend to be tied to source names.
- Late and duplicate events. For streaming pipelines, Microsoft's guidance is to use checkpointing, so every event is still processed at least once after a failure, and to make transformations idempotent, so a repeated run gives the same result and duplicates do no harm. It also advises watermarking, a lateness threshold for late or out-of-order events, and sending messages that cannot be processed to a dead-letter queue.
- Backfills. When logic changes or a source sends corrected history, Airflow lets you backfill Dag runs to process historical data or rerun only the failed tasks. On the transformation side, dbt lets teams build idempotent transformations, which are safe to rerun and produce consistent results.
- Cost of compute. According to AWS, batch pipelines run infrequently, typically during off-peak hours, and need high computing power for a short period. Stream processing pipelines run continuously but need low computing power. This is AWS's general description, and the real compute cost of a batch or streaming pipeline depends on the workload and the tool. Dataflow, for example, bills for the compute resources a job uses. It also lets streaming pipelines that can tolerate duplicates switch to at-least-once mode to reduce cost and latency.
- Silent failures. Azure Data Factory has built-in monitoring through Azure Monitor, the API, PowerShell, Azure Monitor logs and Azure portal health panels. AWS adds that batch pipelines can retry failed steps automatically instead of rerunning the whole job.
A run that finishes without errors can still deliver wrong data: an expired token or a moved source can return zero rows, a changed date format can turn a column into nulls, and a file that lands after the nightly run is left out. Check the output as well as the run, starting with the tables people actually use: row counts in the usual range, a newest record no older than one run interval, no unexpected empty values in key columns and daily totals that match the source system. One user on r/automation described a daily report that ran without errors "for 6 weeks producing blank files before anyone noticed the data source moved."
Benefits and use cases of data pipelines
AWS says pipelines help remove data silos and make analytics more reliable and accurate. They standardize formats such as dates and phone numbers, check for input errors and let data engineers automate repetitive transformation tasks. AWS calls a pipeline that combines data from multiple sources into one view a data integration pipeline. One example is merging CRM and billing records into one record per customer.
Common uses include:
- Dashboards and analysis. IBM says pipelines underpin dashboards and reports and give analysts and data scientists accurate, up-to-date datasets.
- Machine learning. IBM says pipelines deliver high-quality data to machine learning models for training and inference.
- Fraud detection. IBM says pipelines process transaction and user activity data in near real time for fraud detection systems.
- Real-time analytics and operations. The Kafka documentation lists processing payments in real time, tracking fleets and shipments and analyzing sensor data from IoT devices among event streaming uses.